Category: cybersecurity

  • RDP Port: TCP 3389, UDP, Configuration, and Security

    RDP Port: TCP 3389, UDP, Configuration, and Security

    You reach a Windows desktop or server over Remote Desktop Protocol (RDP), and that connection lands on one well-known listener unless someone changed it. Remote Desktop listens on TCP port 3389 by default, and modern Windows versions also use UDP port 3389 for faster session traffic; an RD Gateway moves the public side of the connection to TCP 443 and UDP 3391. Knowing which port is in play on your host tells you what to open, what to test, and what to lock down.

    A laptop and desktop computer connected in an office.

    The same number that makes remote desktop easy to reach also makes it easy to find. Port 3389 is one of the most scanned ports on the internet, and an exposed listener draws brute-force attempts within hours of going live.

    At PacketTools, the guidance below comes from the same checks used on production networks: confirming the rdp port a host listens on, proving reachability from the outside, changing the listener without locking yourself out, and keeping access restricted once it works.

    Which Ports Does Remote Desktop Use by Default?

    A desktop computer connected to a network switch with one port illuminated.

    A standard Windows or Windows Server host accepts Remote Desktop Protocol connections on port 3389 over both TCP and UDP. TCP carries the session setup and acts as the guaranteed path, while UDP speeds up graphics and input when the network allows it.

    Scenario Port(s) Protocol
    Direct RDP to a Windows host 3389 TCP and UDP
    RD Gateway, public side 443 / 3391 TCP / UDP
    RD Gateway to internal hosts 3389 TCP and UDP
    xrdp on Linux (default) 3389 TCP

    Why Does RDP Use TCP 3389 and UDP 3389?

    Microsoft registered 3389 for Terminal Services, and the RDP server has kept it ever since. The server listens on TCP port 3389 and UDP port 3389 out of the box.

    TCP 3389 handles the handshake: security negotiation, TLS, Network Level Authentication, and the initial session channels. Once the session is up, the RDP client and server try to add a UDP transport on the same port number. UDP avoids the retransmission stalls that hurt TCP on lossy or high-latency links, so scrolling, video, and typing feel more responsive.

    When you open firewall rules for a direct connection, allow both protocols on 3389. Microsoft lists TCP and UDP 3389 as the standard RDP port, configurable to a different number on both host and client.

    Does Remote Desktop Still Work When UDP Is Blocked?

    Yes. If UDP 3389 is filtered anywhere along the path, the session falls back to TCP only and still connects.

    You will notice the difference on poor links. Over a clean LAN, TCP-only sessions feel nearly identical. Over Wi-Fi with packet loss or a long WAN path, expect laggier screen updates. In the Remote Desktop Connection client, the connection info icon in the top bar shows whether UDP is active.

    Some VPNs behave badly with RDP over UDP, producing freezes or random disconnects. If a session over VPN keeps hanging, disabling the UDP transport on the client through Group Policy (“Turn Off UDP On Client”) is a practical test.

    Do Windows, Linux, and Other Clients Use Different Ports?

    No. The port belongs to the server, and every client connects to whatever the server listens on.

    • Windows: mstsc.exe and the Windows App default to 3389.
    • macOS and iOS: Microsoft’s Windows App also targets 3389 unless you append a port.
    • Linux clients: Remmina and FreeRDP use 3389 by default, with /v:host:port or a port field for custom values.
    • Linux servers: xrdp listens on TCP 3389 by default, set in /etc/xrdp/xrdp.ini.

    If you run xrdp and Windows hosts behind the same public address, each needs its own external port or a gateway in front.

    How Do RD Gateway and RDS Change the Connection Path?
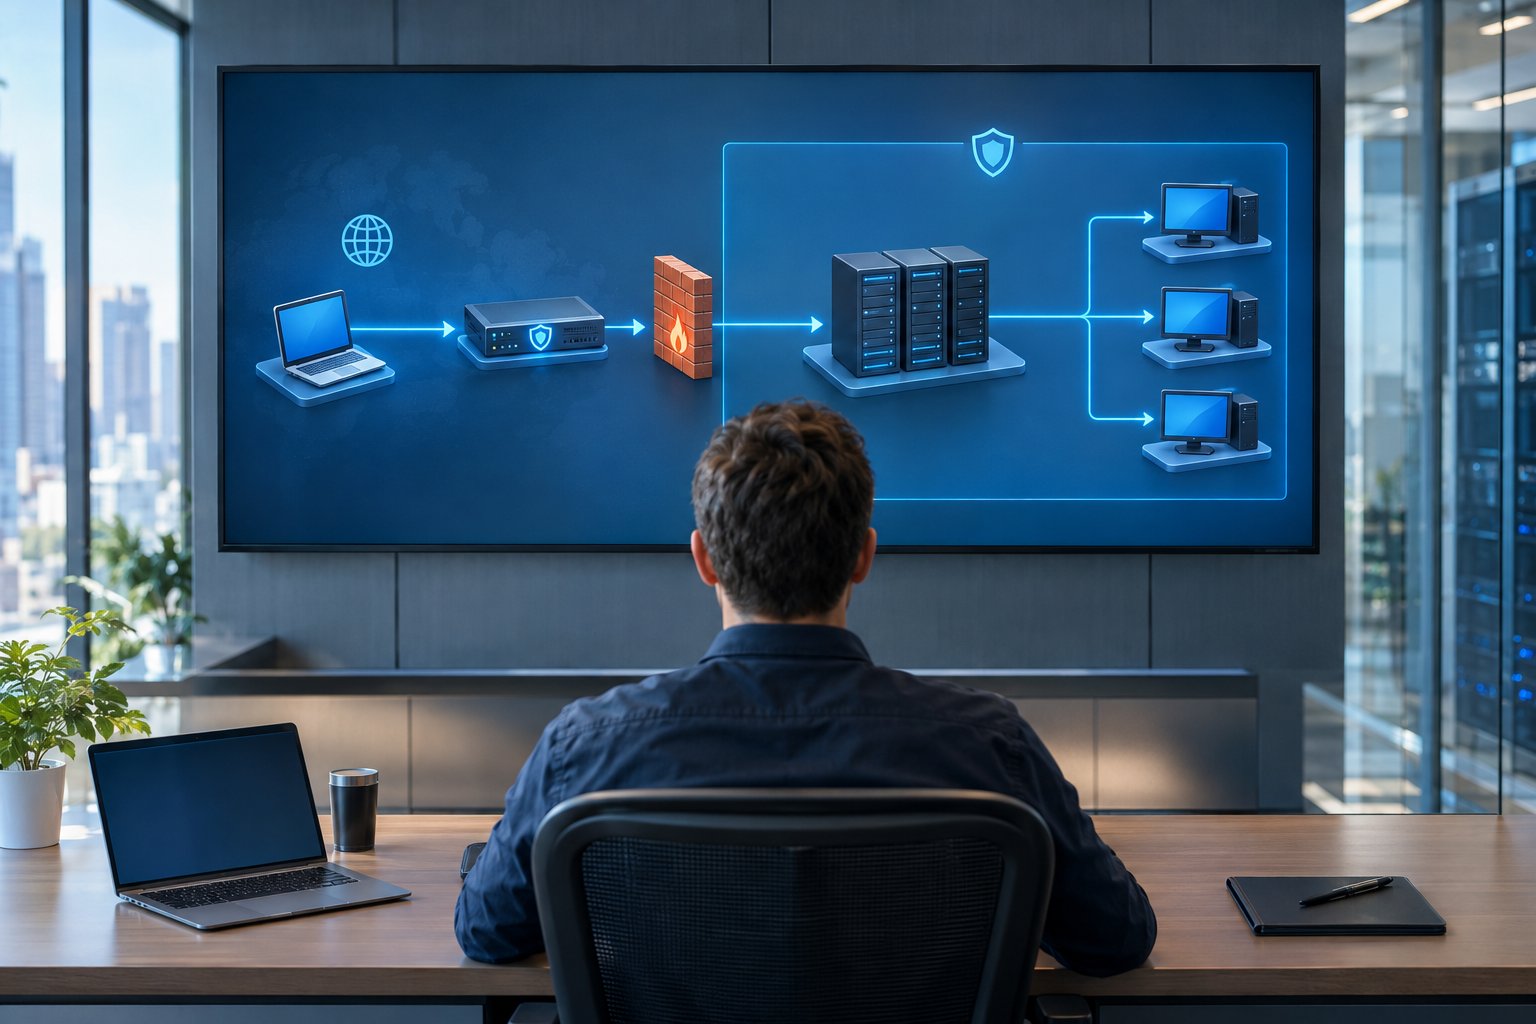
    A network administrator views a diagram of a laptop connecting through a gateway and remote desktop servers to office computers.

    RD Gateway puts an HTTPS front door in front of your hosts, so the internet sees TCP 443 and UDP 3391 while 3389 stays internal. Full Remote Desktop Services (RDS) deployments add more roles, each with its own internal ports for brokering, web feeds, and licensing.

    When Does RD Gateway Use TCP 443 and UDP 3391?

    Every gateway connection starts on TCP 443. Clients reach the gateway over TCP 443 for HTTP over SSL and UDP 3391 for RDP over UDP, and both ports can be changed in RD Gateway Manager.

    The gateway then talks to internal hosts on TCP and UDP 3389. Your perimeter firewall only needs 443 (plus optional 3391) pointed at the gateway, and 3389 never faces the internet.

    Certificates make or break this setup. The gateway first establishes an encrypted SSL tunnel using a certificate the client recognizes, then authenticates the user and can use RADIUS for multi-factor authentication. Use a publicly trusted certificate in production, or every client needs your private chain installed.

    If UDP 3391 is blocked, sessions still work over 443 at reduced responsiveness, mirroring the direct-connection fallback.

    How Do RD Web Access and RemoteApp Fit In?

    RD Web Access publishes desktops and RemoteApp programs as a feed over HTTPS on TCP 443. Users sign in to the web portal or subscribe from the Windows App, then launch resources that open through the gateway.

    RemoteApp uses the same RDP channel as a full desktop; only the presentation differs, with a single application window on the user’s screen. From a firewall view, a RemoteApp launch generates identical traffic to a desktop session: 443 to the gateway, then 3389 internally.

    Internally, RD Web Access reaches the Connection Broker on TCP 5504 for centralized publishing.

    Which Additional Ports Are Specific to RDS Roles?

    Internal role-to-role traffic is where segmented networks break RDS. The common ones:

    • Connection Broker: TCP 5504 to RD Web Access, TCP 3389 to session hosts, TCP 445 plus RPC to session and virtualization hosts.
    • RD Gateway internal: TCP 88 (Kerberos), TCP 135 (RPC Endpoint Mapper), TCP/UDP 389 (LDAP), TCP/UDP 53 (DNS), UDP 1812 and 1813 when NPS handles RADIUS.
    • RDS Licensing: TCP 135 plus dynamic RPC on TCP 49152 to 65535 on Windows Server 2008 and later, TCP 445, and TCP 443 to the Microsoft Clearing House.
    • Administration: TCP 5985 for WMI and PowerShell Remoting across every role.

    If session hosts cannot find a license server, check RPC first. A firewall that allows 135 but blocks the dynamic range produces exactly that symptom.

    How Can You Check the Listener and Troubleshoot Connectivity?

    Start on the host to confirm what it listens on, then test from the client side to prove the path is open. Splitting the problem this way tells you whether to look at the server, the network, or the credentials.

    Find the Configured Listening Port With PowerShell and netstat

    The configured port lives in the registry. In an elevated PowerShell window, run:

    Get-ItemProperty -Path 'HKLM:SYSTEMCurrentControlSetControlTerminal ServerWinStationsRDP-Tcp' -Name PortNumber

    That shows the configured value. To confirm the service is bound to it, check live sockets:

    netstat -ano | findstr ":3389"

    Look for a LISTENING line on 0.0.0.0:3389 and [::]:3389. Match the PID against TermService with tasklist /svc /fi "PID eq <pid>".

    If nothing listens, run qwinsta. Microsoft’s guidance says that if the list shows rdp-tcp with a status of Listen, the listener works. Also confirm TermService and UmRdpService are running, and that a GPO is not setting fDenyTSConnections to 1.

    Test TCP Reachability With Test-NetConnection

    From the client, run:

    Test-NetConnection server01.corp.local -Port 3389

    TcpTestSucceeded : True proves a TCP handshake completed from that machine to that port. It says nothing about UDP, credentials, or whether a session will start.

    When the result is False, the output still helps. A PingSucceeded of True with a failed TCP test points at a firewall or a stopped listener. A failed name resolution line points at DNS. For testing from outside your network, the PacketTools open port checker shows whether 3389 or your custom port is reachable from the public internet, which is often the very exposure you want to rule out.

    Separate DNS, Routing, Firewall, and Sign-In Failures

    Work through the stages in order and repeat the same test after each change:

    1. DNS: Does the name resolve to the right IP? Compare Resolve-DnsName output against the host’s real address. Stale records after a migration are common.
    2. Routing: Can you reach the subnet? Traceroute shows where packets stop.
    3. Firewall: Check Windows Firewall rules for “Remote Desktop – User Mode (TCP-In)” on the active profile, then any perimeter, NSG, or VPN filter.
    4. Listener: Confirmed with netstat and qwinsta above.
    5. Sign-in: If the port answers but you get credential or NLA errors, the network is fine. Check group membership in Remote Desktop Users, account lockout, and certificate warnings.

    That staged approach is the core of solid network troubleshooting: each test isolates one layer before you touch configuration.

    How Do You Change the Listening Port Without Losing Access?

    Change the registry value, open the new port in every firewall, and only then restart Remote Desktop Services. Getting that order wrong on a remote host is the classic way to cut off your own session.

    Choose an Unused Port and Prepare a Recovery Path

    Pick a port in the registered range (1024 to 49151) and stay away from well-known ports below 1024. Confirm nothing else uses it:

    netstat -ano | findstr ":3390"

    An empty result means it is free. Avoid ports your other applications may claim later, and document the choice.

    Before touching anything, line up a second way in: a hypervisor or cloud serial console, iLO/iDRAC, or a working PowerShell Remoting session on TCP 5985. On a VPS with only RDP access, this step is the difference between a two-minute fix and a support ticket.

    Update PortNumber With PowerShell or Registry Editor

    With PowerShell as administrator:

    Set-ItemProperty -Path 'HKLM:SYSTEMCurrentControlSetControlTerminal ServerWinStationsRDP-Tcp' -Name PortNumber -Value 3390

    In Registry Editor, browse to the same RDP-Tcp key, open the PortNumber DWORD, select Decimal, and enter the new value. Entering it while Hexadecimal is selected is a frequent mistake that produces a completely different port.

    The change does nothing until TermService restarts. The custom RDP port applies to both TCP and the UDP port used for the faster transport.

    Scope Firewall Rules Before Restarting Remote Desktop Services

    Microsoft’s procedure adds inbound TCP and UDP rules for the new port with New-NetFirewallRule. Add a source restriction so the rule admits only your management networks:

    New-NetFirewallRule -DisplayName 'RDP-3390-TCP' -Direction Inbound -Protocol TCP -LocalPort 3390 -RemoteAddress 10.20.0.0/24 -Action Allow
    New-NetFirewallRule -DisplayName 'RDP-3390-UDP' -Direction Inbound -Protocol UDP -LocalPort 3390 -RemoteAddress 10.20.0.0/24 -Action Allow

    Update any cloud security group, router NAT, or perimeter firewall too. Then restart the service:

    Restart-Service TermService -Force

    Your current session drops at this point. That is expected.

    Connect With mstsc.exe and Verify the New Port

    Reconnect with the port appended: mstsc.exe /v:server01:3390, or type server01:3390 in the Remote Desktop Connection address box.

    Confirm the result from both sides. On the host, netstat -ano | findstr ":3390" should show LISTENING. From the client, Test-NetConnection server01 -Port 3389 should now fail and port 3390 should succeed. Once confirmed, disable the old built-in Remote Desktop rules so 3389 is not left open by accident.

    How Do You Secure Remote Access Beyond Changing the Port?

    A new port number cuts scanner noise, but malicious bots fingerprint RDP on any port within minutes. Real RDP security comes from limiting who can reach the listener at all, then hardening authentication for those who can.

    Keep Public RDP Behind a VPN or Hardened RD Gateway

    Never publish rdp port 3389, or any custom port, directly to the internet. Exposed RDP remains a leading entry point for ransomware operators, who buy stolen credentials and spray them at open listeners.

    Your realistic options:

    • VPN: Users connect to the network first; RDP is reachable only from VPN address pools.
    • RD Gateway: One hardened HTTPS endpoint with RD CAPs and RD RAPs controlling who reaches which host, plus MFA through NPS and RADIUS.
    • SSH tunnel: Workable for a few admins: forward a local port to the host’s 3389 over an SSH bastion.

    Patch the gateway or VPN appliance aggressively. It becomes the exposed surface in place of every individual host.

    Require NLA, Validate TLS, and Enforce Strong Authentication

    Network Level Authentication (NLA) forces users to authenticate before the server builds a session, which blocks unauthenticated attackers from consuming resources or reaching pre-auth bugs. Enable it in System Properties or via Group Policy under Remote Desktop Session Host > Security.

    Replace the self-signed certificate with one from your internal CA or a public CA, and set the security layer to TLS. Users who learn to click through certificate warnings will click through a spoofed one too.

    Pair this with MFA at the gateway or VPN, an account lockout policy, and Windows LAPS so local administrator passwords differ on every machine.

    Use Group Policy, Restricted Firewall Rules, and Access Monitoring

    Group Policy keeps these settings consistent across hundreds of hosts: NLA required, TLS security layer, session timeouts, and Remote Desktop Users limited to specific groups.

    Scope firewall rules by source address everywhere, including inside the LAN, so workstations cannot RDP laterally to servers. Jump hosts or privileged access workstations make good sole sources.

    Watch the logs. Event ID 4625 with logon type 10 or 3 flags failed RDP sign-ins, and 4624 type 10 shows successful ones. A spike from one IP or many accounts is brute forcing; forward these events to your SIEM and alert on them.

    Verify the Connection Path and Keep RDP Access Restricted

    RDP listens on TCP and UDP 3389 by default, with TCP as the guaranteed path and UDP as the performance layer. RD Gateway shifts the public side to TCP 443 and UDP 3391 while 3389 stays internal.

    Confirm the listener with the registry, netstat, and qwinsta, then prove reachability with Test-NetConnection and an external port check. If you move to a custom port, set firewall rules before restarting TermService and keep a console path ready.

    Treat the port number as a minor detail. Put access behind a VPN or gateway, require NLA and TLS, scope firewall rules to known source addresses, and alert on failed logon events.

  • TP-Link Default Password: Find Your Login and Restore Access

    TP-Link Default Password: Find Your Login and Restore Access

    Your TP-Link router has two credentials that are easy to confuse. One is the admin password, which opens the router’s settings page. The other is the Wi-Fi password, which lets your devices join the network. Mixing them up is the most common reason a login attempt fails.

    A person configures a wireless router beside a laptop.

    For the tp link default password, older TP-Link routers use “admin” as both the username and password. Newer models have no default login and ask you to create your own admin password the first time you sign in. Your default Wi-Fi name and key are printed on the label on the router. If the admin password you set is lost, recovery depends on what you configured ahead of time. Without a recovery option, you need a factory reset.

    At PacketTools, we troubleshoot this kind of access problem in production networks all the time. Below, you can work out which credential applies to you, reach the login page, and try every recovery path before you wipe your configuration.

    Which Credentials Does Your Router Actually Use?

    A person checks the label on a home Wi-Fi router beside a laptop.

    Your router’s age, your firmware, and whether you linked a TP-Link ID together decide what the login screen accepts. Some routers from internet service providers add their own credentials on top of these.

    Older Models May Use admin/admin; Newer Models Require Your Own Password

    Older TP-Link routers ship with admin as the username and admin as the password. On these models, the login form shows two fields, and sometimes both are pre-filled.

    Newer models have no shared default. TP-Link confirms that newer router models require you to create a custom admin password on first login, while older ones keep “admin” for both fields. If your login screen shows a single password box with no username field, you have the newer style. In that case, typing “admin” will not work unless you chose it yourself.

    A quick way to tell which type you have:

    Login screen shows Likely model type What to enter
    Username + password fields Older admin / admin (unless changed)
    Single password field Newer The password you created
    “Create password” prompt New or freshly reset Choose a new password
    TP-Link ID toggle Cloud-linked Your TP-Link ID email and password

    How Do Admin, Wi-Fi, and TP-Link ID Passwords Differ?

    Three separate passwords can exist on one router:

    • Admin (local management) password: opens the web interface at tplinkwifi.net or the router’s IP address.
    • Wi-Fi password (wireless key): joins your devices to the network identified by its SSID.
    • TP-Link ID password: your cloud account, used by the Tether and Deco apps and for remote management.

    TP-Link support staff stress that the password requested on first access is the router’s management password, not your TP-Link ID password and not your Wi-Fi password. One detail catches people out. Once a cloud router is bound to a TP-Link ID, the local login password you created becomes ineffective, and you sign in with the TP-Link ID instead.

    A useful test: if your phone still connects to Wi-Fi but the admin page rejects you, your problem is the admin password. If you cannot join the network at all, the problem is the wireless key.

    Where Can You Find Model-Specific or ISP Login Details?

    Check the router itself first. Default credentials sit on a label on the back or bottom of the device under headings such as Default Access, Default Settings, or Default Wireless Access. The same details appear in the Quick Installation Guide that came in the box.

    Routers supplied by your internet provider are different. ISPs often ship TP-Link hardware with custom firmware, a different login address, or an account-specific password. If your label carries the ISP’s logo or lacks a “Default Access” block, the provider’s support documentation or help line holds the correct details. Some ISP units also lock certain settings no matter which password you use.

    How Do You Open the Router’s Login Page?

    A person uses a laptop beside a Wi-Fi router.

    Connect to the router, then type tplinkwifi.net or its local IP into the address bar. If neither address loads, look up the default gateway your computer received and use that.

    Connect to the Router by Ethernet or Wi-Fi

    The management page runs on the router itself, so it works without internet service. Your device does need to be on the router’s own network.

    • Ethernet: plug into one of the yellow LAN ports, not the WAN/internet port. Confirm the matching LAN LED lights up.
    • Wi-Fi: join the router’s SSID. On a fresh or reset unit, use the network name and key from the label.

    A wired connection is the safer choice when you plan to change wireless settings. If you edit the SSID or password over Wi-Fi, your session drops the moment you save.

    Open tplinkwifi.net or the Router’s Local IP Address

    Use Chrome, Firefox, or Edge, and type one of these directly into the address bar:

    1. tplinkwifi.net
    2. 192.168.0.1
    3. 192.168.1.1 (common on older and ISP models)

    If you type the address into a search box, you get search results and never reach the login page. The tplinkwifi.net name only resolves while you are connected to a TP-Link router. On a mesh system or a MiFi hotspot, the hostname differs, and the label lists the right one.

    Find the Actual Gateway Address When the Defaults Fail

    If someone changed the LAN subnet, neither default address works. Your computer already knows the real one, listed as the default gateway:

    • Windows: run ipconfig and read “Default Gateway.”
    • macOS: run route -n get default | grep gateway, or check System Settings > Network > Details > TCP/IP.
    • Linux: run ip route | grep default.
    • iPhone/Android: open the connected Wi-Fi network’s details and look for “Router” or “Gateway.”

    Type that address into the browser. If you want to know more about how gateways are assigned, our guide to your router IP address covers the private ranges routers use and why some units hand out 10.x or 172.16.x addresses.

    Where Can You Find or Change the Wi-Fi Password?

    The router label holds the factory Wi-Fi key, and the wireless settings page shows whatever key is set now. MiFi hotspots use their own login address and app.

    Check the Label for the Original Network Name and Wireless Key

    On most TP-Link routers, the label lists the default SSID and wireless password. On many models, the default SSID is TP-Link_XXXX and is case-sensitive, with the last characters drawn from the MAC address.

    The label only helps if nobody changed the settings. If the network name broadcasting near you differs from the label, the key has almost certainly changed too. Dual-band routers often list a separate “_5G” SSID that uses the same key.

    View or Update the Password in Wireless Settings

    After you log in to the admin page, the menu path depends on firmware. TP-Link lists Wireless > Wireless Settings or Basic > Wireless as the usual locations. Some older models split the SSID onto Basic Settings and the key onto Wireless Security.

    To change it:

    1. Open the wireless page and select the password field (some firmware hides it behind an eye icon).
    2. Enter a new key of at least 12 characters, mixing letters, numbers, and symbols.
    3. Use WPA2-PSK or WPA2/WPA3 mixed mode if your devices support it.
    4. Save, then reconnect each device with the new key.

    On dual-band routers, check whether each band has its own key field.

    Find Mobile Wi-Fi Details Using tplinkmifi.net or the tpMiFi App

    TP-Link’s portable M-series hotspots use tplinkmifi.net in place of tplinkwifi.net. Connect to the hotspot, open that address, and the wireless menu shows the SSID and key. Many units print the default key under the battery cover, and some show it on their screen.

    The tpMiFi app for iOS and Android does the same job from your phone. Once connected, it shows the network name and password, along with battery level and data usage.

    What Should You Check When the Login Page Will Not Load?

    Most failures come down to your device sitting on the wrong network or subnet, or to something on your device blocking local traffic. Work from the network layer up before you suspect the router.

    Check Local Addressing and Test Gateway Reachability

    Your device needs an address from the router’s DHCP pool. Run ipconfig or ip addr and compare it with the gateway:

    • 192.168.0.x pairs with gateway 192.168.0.1.
    • 192.168.1.x pairs with gateway 192.168.1.1.
    • 169.254.x.x means DHCP failed, so you have no working connection to the router.

    Next, run ping 192.168.0.1 (or your gateway). Replies mean the router is alive and the problem lies in the browser or in security software. TP-Link notes that firewall or antivirus software can block access to the router. No replies point to cabling, a wrong subnet, or a static IP set on your adapter. Our IP address basics guide explains subnets and why mismatched ranges cannot talk to each other.

    Rule Out Guest Network Isolation, VPN Routing, and Mobile Data

    Three common traps block access even when your Wi-Fi icon looks healthy:

    • Guest network: guest SSIDs block access to the admin page by design. Switch to the main network.
    • VPN or proxy: a full-tunnel VPN sends 192.168.x.x traffic down the tunnel. Disconnect it, or enable your client’s local network access option.
    • Mobile data: phones sometimes fall back to cellular when Wi-Fi has no internet. Turn off mobile data while you log in.

    Corporate laptops with always-on VPN agents are the usual culprit. Test from a personal device first.

    Troubleshoot Browser Sessions and Verify Certificate Warnings

    Stale cookies and cached redirects can leave the login page blank or stuck in a loop. Open a private window, try another browser, or clear site data for tplinkwifi.net. Disable any extensions that rewrite pages.

    A “Your connection isn’t private” warning is expected. The router uses a self-signed certificate, so click Advanced and proceed. Check that the address bar shows your actual gateway IP or tplinkwifi.net before you continue. A warning on any other hostname deserves suspicion.

    Separate Local Router Access Problems From Internet Connectivity Faults

    The admin page and your internet connection are separate paths. If the gateway answers ping but websites fail, the fault sits upstream at the WAN link, the modem, or the ISP. If the gateway does not answer, the internet is irrelevant until local access works.

    Once you are online, the PacketTools What Is My IP tool confirms your public address, and Ping Test and Traceroute show whether traffic leaves your network cleanly. These run from our servers, so they test the public side and cannot reach your private 192.168 gateway. Use your computer’s own ping for that. Our network troubleshooting guides follow this same layered order through DNS and latency.

    How Can You Recover Access Before Factory Resetting?

    Check stored credentials, any recovery feature you enabled earlier, a linked TP-Link ID, and your ISP before you reset. A reset always works, but it costs you every setting on the router.

    Check Saved Passwords and Supported Recovery Options

    Start with the places a password may already be stored:

    • Browser password storage: Chrome, Edge, Firefox, and Safari often saved the router login. Search for “192.168” or “tplinkwifi.”
    • Password manager: search your vault for the router model or “admin.”
    • Setup notes: check the Quick Installation Guide card, a photo of the label, or IT documentation.
    • Logged-in devices: a tablet or the Tether app may still hold an active session.

    Then look for Forgot Password? on the login page. It works only if you set up recovery beforehand. TP-Link’s feature supports recovery by email or security questions, configured under Advanced > System Tools > Administration. Email recovery is disabled when you log in with a TP-Link ID.

    Try a Previously Linked TP-Link ID or Contact Your ISP

    If you ever bound the router to a TP-Link ID, the login screen offers a toggle. Your cloud account credentials let you in, and you can reset the TP-Link ID password through TP-Link’s account site. Open the Tether app as well, since a linked account often lists the router there.

    For ISP-supplied hardware, call the provider before you reset. ISPs can often push credentials remotely, and a reset can erase the PPPoE username, VLAN tags, or VoIP settings your service depends on.

    Prepare for Lost Settings and Follow the Model’s Reset Instructions

    A factory reset erases the internet connection type, Wi-Fi name and key, port forwards, DHCP reservations, and the admin password. Before you start, write down the details you will need:

    1. ISP login details (PPPoE username and password, or static IP data).
    2. SSIDs and keys, so you can reuse them and avoid reconnecting every device.
    3. Port forwarding and reservation rules.

    With the router powered on, press and hold the Reset button for about 10 seconds until the LEDs flash, then wait for a full reboot. Some models use a pinhole button, and mesh units may need a different hold time, so check the model’s manual. Clearing settings on your computer side can also help when old profiles linger, and our guide on how to reset network settings covers Windows, macOS, and mobile devices. Router setup afterward takes approximately 5 to 10 minutes.

    Set Distinct Passwords and Reconnect Devices Securely

    When the setup wizard asks, give each credential its own value. The admin password, Wi-Fi key, and TP-Link ID password should never match, because anyone who joins your Wi-Fi would otherwise have router control too.

    Store all three in a password manager right away. Enable Password Recovery while you are logged in, and update the firmware. If you keep the old SSID and key, most devices reconnect on their own. Smart home gear stuck on 2.4 GHz sometimes needs to be re-paired.

    Restore Access Without Unnecessary Resets

    Most TP-Link lockouts come down to the wrong credential. Older units accept admin/admin, newer ones expect the password you created, and the label covers only the factory Wi-Fi key.

    Work through the problem in order. Confirm you are on the main network with no VPN running, and find your real gateway. Ping it locally, then try saved passwords, Forgot Password?, or your TP-Link ID. Reset only when all of those fail, and record your ISP details first. After that, the PacketTools diagnostics confirm that your public connection, DNS, and routing came back cleanly.

  • Change DNS Settings on Windows, Mac, Mobile, and Routers

    Change DNS Settings on Windows, Mac, Mobile, and Routers

    PacketTools runs browser-based DNS diagnostics without logging a single query, and the same habits that keep those tools honest apply to your own machines: know which resolver answers your lookups, change it on purpose, and confirm the result. To switch, open your device’s network settings, set DNS from automatic to manual, and enter a primary and secondary resolver address.

    A network administrator adjusts a laptop beside a wireless router.

    To change DNS settings, open the network adapter or Wi-Fi properties on your device (or the WAN/Internet page on your router), switch DNS assignment to Manual, and enter a trusted resolver pair such as Cloudflare’s 1.1.1.1 and 1.0.0.1 or Google Public DNS’s 8.8.8.8 and 8.8.4.4. A device-level change affects one machine and is easy to undo. A router change pushes the new resolver to every device that gets its address from the router.

    Every step below includes the path back to your original configuration. A DNS change that breaks name resolution looks exactly like an internet outage, so the rollback is as important as the switch.

    When Does a Different DNS Resolver Help?

    A person reviews network settings on a laptop beside a wireless router.

    A different resolver helps when your current DNS server is slow, unreliable, filtering things you don’t want filtered, or keeping logs you’d prefer it didn’t. The domain name system translates a domain name into an IP address, and by default your device asks whichever DNS server your internet service provider (ISP) hands out through DHCP.

    Swapping that server changes who answers your lookups and what policies they apply. It leaves your connection speed, routing, and public address untouched.

    What Can a DNS Change Fix, and What Can’t It?

    A resolver change fixes problems that live in the lookup step. Good candidates include:

    • ISP resolver outages or timeouts, where pages hang on “Resolving host” while ping to a numeric address works fine
    • Stale or incorrect answers from a poorly maintained ISP cache
    • Unwanted ISP redirection, such as typo domains landing on an ad-filled search page
    • Missing security filtering, when you want a resolver that blocks known malware and phishing domains
    • Privacy preferences, when you’d rather send queries to a provider with a published no-logging policy

    A DNS change does not increase internet bandwidth, encrypt all internet traffic, or change your public IP address. Packet loss, a weak Wi-Fi signal, a saturated uplink, and a down fiber line all stay exactly as they were. If you’re fuzzy on how addressing and name resolution fit together, the basics of IP addresses clear that up quickly.

    A quick test separates the two: if ping 1.1.1.1 succeeds but ping packettools.com fails, you have a DNS problem. If both fail, start broader network troubleshooting before touching resolver settings.

    Which Public DNS Servers Should You Consider?

    Public DNS servers from large providers run anycast networks with redundant nodes, which is why they’re common choices for a switch. These are the published addresses for the most widely used options:

    Provider IPv4 primary IPv4 secondary IPv6 primary Notable for
    Cloudflare 1.1.1.1 1.0.0.1 2606:4700:4700::1111 Speed, privacy policy
    Google Public DNS 8.8.8.8 8.8.4.4 2001:4860:4860::8888 Reliability, global reach
    Quad9 9.9.9.9 149.112.112.112 (provider-published) Malware and phishing blocking
    OpenDNS (Cisco) 208.67.222.222 208.67.220.220 2620:119:35::35 Content filtering
    OpenDNS FamilyShield 208.67.222.123 208.67.220.123 (provider-published) Adult content blocking

    Pick one provider and use its own primary and secondary pair. Mixing a filtering resolver with a non-filtering one produces inconsistent results, because your device may fall back to the secondary and skip the filter entirely.

    Read the provider’s current privacy and logging policy before you commit. Public resolvers differ in what they keep, and speed claims say nothing about data handling.

    How Do You Set DNS on Windows 11 and Windows 10?

    Windows gives you four routes: the Settings app, the classic Control Panel, PowerShell, and netsh in Command Prompt. All of them write the same per-adapter setting, so choose the one that fits whether you’re fixing one laptop or scripting a fleet. Changing DNS requires an administrator account.

    Before you start, run ipconfig /all and note the current DNS Servers line for your active adapter. That’s your rollback record.

    Use the Windows 11 Settings App for Wi-Fi or Ethernet

    To change DNS on Windows 11 through the Settings app:

    1. Right-click Start and choose Settings.
    2. Select Network & internet.
    3. For Wi-Fi, choose Wi-Fi, then Hardware properties (or your network’s properties). For a wired link, choose Ethernet.
    4. Next to DNS server assignment, click Edit.
    5. Change the dropdown from Automatic (DHCP) to Manual.
    6. Turn on IPv4.
    7. Enter the Preferred DNS address (for example, 1.1.1.1) and the Alternate DNS address (1.0.0.1).
    8. Click Save.

    The setting applies per network. If you set it on your home Wi-Fi, a coffee shop network or your Ethernet adapter still uses whatever DHCP hands out. Switching back means returning the dropdown to Automatic (DHCP). If you’ve ever set a static address on that adapter, the difference between DHCP and static IP assignment explains why the DNS fields sometimes stay locked to manual.

    Use Control Panel on Windows 10 or Windows 11

    The Control Panel route works on both versions and exposes the classic TCP/IPv4 dialog many admins prefer:

    1. Open Control Panel and go to Network and Sharing Center.
    2. Click Change adapter settings.
    3. Right-click your active network adapter and choose Properties.
    4. Select Internet Protocol Version 4 (TCP/IPv4) and click Properties.
    5. Choose Use the following DNS server addresses.
    6. Fill in Preferred DNS server and Alternate DNS server.
    7. Click OK, then Close.

    A tip from production work: tick Validate settings upon exit if you see it. It won’t catch a typo in a resolver address, but it flags a broken adapter configuration before you close the window and lose your connection.

    Use PowerShell or Command Prompt for Repeatable Changes

    PowerShell is the fastest way to make the same change across machines. Open Terminal (Admin) and find your interface index:

    Get-NetIPConfiguration

    Then set the servers with Set-DnsClientServerAddress, replacing 6 with your index:

    Set-DnsClientServerAddress -InterfaceIndex 6 -ServerAddresses 1.1.1.1,1.0.0.1

    To roll back to DHCP-assigned DNS:

    Set-DnsClientServerAddress -InterfaceIndex 6 -ResetServerAddresses

    In Command Prompt (run as administrator), netsh does the same job using the adapter name:

    netsh interface ipv4 set dnsservers name="Wi-Fi" static 1.1.1.1 primary
    netsh interface ipv4 add dnsservers name="Wi-Fi" 1.0.0.1 index=2

    Revert with netsh interface ipv4 set dnsservers name="Wi-Fi" source=dhcp. Adapter names must match exactly, so run netsh interface show interface first if you’re unsure.

    Configure IPv6 and DNS over HTTPS Where Supported

    If your ISP gives you IPv6 connectivity, set IPv6 resolvers too. Otherwise your device keeps asking the ISP’s IPv6 DNS server for some lookups, and your change only half applies. In the Windows 11 Edit DNS settings window, toggle IPv6 on and enter the provider’s IPv6 pair, such as 2606:4700:4700::1111 and 2606:4700:4700::1001 for Cloudflare. In Control Panel, the same fields sit under Internet Protocol Version 6 (TCP/IPv6).

    Windows 11 also supports DNS over HTTPS, which encrypts lookups between your PC and the resolver. After entering a recognized resolver address in Settings, the DNS over HTTPS dropdown appears under each server. Choose On (automatic template) to encrypt queries to providers Windows knows, including Cloudflare, Google, and Quad9. Run netsh dns show encryption to list the resolvers Windows has templates for.

    How Do You Set DNS on Other Devices and Your Router?

    A person configures a laptop beside a Wi-Fi router, smartphone, and tablet.

    Every platform stores a DNS server address per network connection, and each has both a graphical path and, on desktops, a command-line equivalent. Mobile devices add encrypted “Private DNS” options that take a hostname, while routers push your choice to every client.

    Update DNS on macOS

    On macOS Ventura and later:

    1. Open Apple menu > System Settings > Network.
    2. Select Wi-Fi or Ethernet, then click Details next to your connected network.
    3. Choose DNS in the sidebar.
    4. Under DNS Servers, click + and enter your primary address, then click + again for the secondary.
    5. Click OK.

    Gray entries are values your router supplied; your manual entries replace them. From Terminal, the same change is one line:

    networksetup -setdnsservers Wi-Fi 1.1.1.1 1.0.0.1

    To return to DHCP-assigned DNS, run networksetup -setdnsservers Wi-Fi Empty. Use networksetup -listallnetworkservices if your service name differs from “Wi-Fi.”

    Update DNS on Linux

    On desktop distributions using NetworkManager (Ubuntu, Fedora, and most others), open Settings > Wi-Fi or Network, click the gear next to your connection, open the IPv4 tab, turn off Automatic DNS, enter comma-separated addresses, and click Apply. Toggle the connection off and on to load the change.

    From the terminal, nmcli is cleaner and scriptable:

    nmcli connection show --active
    nmcli connection modify "Home-WiFi" ipv4.dns "1.1.1.1 1.0.0.1" ipv4.ignore-auto-dns yes
    nmcli connection up "Home-WiFi"

    Revert with ipv4.dns "" ipv4.ignore-auto-dns no. Avoid editing /etc/resolv.conf directly on systemd-resolved systems; it points to a local stub at 127.0.0.53 and gets rewritten.

    Update DNS on iPhone, iPad, and Android

    On iPhone and iPad, DNS is set per Wi-Fi network:

    1. Open Settings > Wi-Fi and tap the (i) next to your network.
    2. Scroll to Configure DNS and choose Manual.
    3. Delete the existing entries, tap Add Server, and enter your addresses.
    4. Tap Save.

    Cellular connections on iOS don’t expose this setting; you’d need a provider’s configuration profile or app for encrypted DNS on mobile data.

    On Android 9 and later, the cleanest option is Private DNS, which applies to Wi-Fi and mobile data and encrypts lookups with DNS over TLS:

    1. Open Settings > Network & internet (Samsung: Connections > More connection settings).
    2. Tap Private DNS and choose Private DNS provider hostname.
    3. Enter a hostname such as one.one.one.one (Cloudflare) or dns.google (Google).
    4. Tap Save.

    Private DNS takes a hostname, so typing 1.1.1.1 into that field fails.

    Update Your Router for Devices Across the Network

    A router change covers smart TVs, consoles, and guest devices you can’t configure individually. Find your router’s IP address from the Default Gateway line in ipconfig (common values are 192.168.1.1 and 192.168.0.1), sign in with the admin credentials, and look for the DNS fields on the WAN or Internet page. Common locations:

    Router brand Typical path
    TP-Link Advanced > Network > Internet (classic UI: Network > WAN)
    Netgear Advanced > Setup > Internet Setup
    Asus WAN > Internet Connection > WAN DNS Setting
    Linksys Connectivity > Internet Settings
    D-Link Setup > Internet > Manual Internet Connection Setup

    Switch from automatic to manual DNS, enter the primary and secondary addresses, and save. Screenshot the original values first.

    Clients keep their old resolver until their lease renews, a detail that makes more sense once you know what DHCP does on your network. Reboot the router or reconnect each device to force it. ISP-rented gateways from some providers lock these fields; in that case, set DNS on each device or put the gateway in bridge mode behind your own router.

    How Can You Verify the New Resolver Is Working?

    Verification takes three checks: confirm the address your device is configured to use, confirm lookups succeed through that resolver, and confirm nothing else on the system is quietly sending queries elsewhere. Saving a setting proves nothing until you’ve seen the new DNS server answer.

    Check the DNS Addresses Assigned to Your Device

    Each platform reports its active resolvers with one command:

    • Windows: ipconfig /all (look for DNS Servers under your active adapter) or Get-DnsClientServerAddress in PowerShell
    • macOS: scutil --dns | grep nameserver
    • Linux: resolvectl status or nmcli device show | grep DNS
    • iPhone/Android: reopen the Wi-Fi details or Private DNS screen; Android shows “Connected” under Private DNS when the hostname validates

    If you changed the router, your device will still list the router’s own address (such as 192.168.1.1) as its DNS server. That’s normal; the router forwards queries upstream, so check the router’s status page or run the external tests below.

    Test Name Resolution and Compare DNS Results with PacketTools

    Run nslookup packettools.com and read the Server and Address lines at the top. They should show your new resolver. On Windows, nslookup contacts only the primary DNS server configured, so use Resolve-DnsName packettools.com to test what the full Windows client does, including fallback to the alternate.

    Query a resolver directly to compare answers: nslookup packettools.com 1.1.1.1 versus nslookup packettools.com 8.8.8.8. Different IPs aren’t automatically a fault; answers differ during the 24-48 hour propagation window after a record change, and CDN-hosted domains return location-based results.

    For an outside view, the PacketTools DNS Propagation Checker queries public resolvers worldwide, and DNS Lookup checks individual record types. Neither logs your queries. A DNS leak test shows which resolver operator the internet sees your lookups coming from, which catches router or ISP interception your local commands miss.

    Account for Browser Secure DNS, VPNs, and Cached Answers

    Your OS setting can be correct while traffic still goes elsewhere. Three common overrides:

    • Browser secure DNS: Chrome, Edge, and Firefox can send lookups over DNS over HTTPS to their own configured provider. Check Settings > Privacy and security > Use secure DNS in Chrome or Edge, and Privacy & Security > DNS over HTTPS in Firefox.
    • VPN clients: most VPNs push their own resolvers while connected, replacing yours until you disconnect.
    • Cached answers: your OS, browser, and router each cache results until the record’s TTL expires, so an old answer can survive a resolver change.

    Test with the VPN off and in a fresh browser window before deciding the change failed.

    What If Sites Stop Resolving?

    A typo in the DNS server address is the most common reason sites stop loading right after a change, followed by setting DNS on the wrong adapter and network policies that block outside resolvers. Work through those before assuming the provider is down.

    Check the Address, Adapter, and Network Policy

    Start with the configuration you just entered:

    1. Re-read the address. 1.1.1.1 typed as 1.1.11 or 8.8.8.8 entered as 8.8.4 makes every lookup time out. Browser errors like DNS_PROBE_FINISHED_BAD_CONFIG point straight at this.
    2. Confirm the adapter. Machines with Wi-Fi, Ethernet, and virtual adapters (Hyper-V, VMware, VPN) often get the change on an inactive interface. Match the adapter in ipconfig /all to the one carrying your default gateway.
    3. Ping the resolver. ping 1.1.1.1 should reply. If it doesn’t, something between you and the resolver is blocking it.
    4. Check network policy. Corporate networks, schools, and some guest Wi-Fi block outbound UDP and TCP port 53 to anything except their own resolvers. Firewalls and endpoint security products do the same locally.

    On a managed work device, Group Policy or MDM can overwrite your DNS settings at the next refresh. Follow your organization’s policy there. Persistent “DNS server not responding” errors on a clean configuration usually mean the resolver is unreachable from your network.

    Clear Cached Results and Restore the Previous DNS Configuration

    Clear stale answers before retesting. Windows checks the cache, then the Hosts file, then the DNS server when resolving names… that order means a cached or hosts-file entry wins every time.

    To flush the DNS cache:

    • Windows: ipconfig /flushdns
    • macOS: sudo dscacheutil -flushcache; sudo killall -HUP mDNSResponder
    • Linux (systemd-resolved): resolvectl flush-caches
    • Chrome/Edge: visit chrome://net-internals/#dns and click Clear host cache

    If lookups still fail, roll back using the values you recorded. Set Windows back to Automatic (DHCP) or run Set-DnsClientServerAddress -ResetServerAddresses, use networksetup -setdnsservers Wi-Fi Empty on macOS, and set iOS Configure DNS back to Automatic. Restore the router’s original WAN DNS values from your screenshot. Once resolution works again, retry the new resolver on a single device to isolate the fault.

    Choose a Resolver, Test It, and Keep a Way Back

    A clean DNS change follows the same order on every platform: write down the current values, set a matched primary and secondary from one provider, and confirm with nslookup or Resolve-DnsName that the new server answers.

    Test on one device first. Move the change to your router only after that device resolves sites reliably for a day, since a router mistake takes down every client on the network.

    Keep your rollback commands handy:

    • Windows: set Automatic (DHCP) or run Set-DnsClientServerAddress -InterfaceIndex <n> -ResetServerAddresses
    • macOS: networksetup -setdnsservers Wi-Fi Empty
    • Linux: clear ipv4.dns and set ipv4.ignore-auto-dns no
    • Router: re-enter the original WAN DNS values from your screenshot

    When results look odd, check browser secure DNS and any active VPN before blaming the resolver. Then compare answers across public resolvers with the PacketTools DNS Propagation Checker and DNS Lookup, and flush local caches once the outside view looks correct.

  • WHOIS IP Lookup: Find the Network Behind an Address

    WHOIS IP Lookup: Find the Network Behind an Address

    Every public IP address on the internet traces back to a registration record, and that record tells you which organization holds the block it sits in. A WHOIS IP lookup queries the regional internet registry responsible for an address and returns the registered organization, the full IP range, and an abuse contact you can use to report traffic. That is often enough to tell a cloud server from a home broadband connection in under a minute.

    A cybersecurity analyst examines a global network map on a computer.

    PacketTools was built by an engineer with over 28 years in enterprise IT, and the same registration checks described here show up daily when verifying VPN endpoints, chasing odd firewall hits, and confirming who owns a netblock before opening a ticket. The record is useful, but it has limits that trip up even experienced admins.

    Once you can read the fields correctly, you will know when to trust the record, when to cross-check it with DNS and routing data, and where to send an abuse report so it reaches someone who can act.

    How Do You Look Up an IP Address or Domain?

    You run a lookup by sending the address or domain name to a WHOIS or RDAP service, either from a web tool or a terminal. IP queries go to a regional internet registry, while domain queries go to the registry and registrar for that top-level domain, so the two searches return different kinds of records.

    Look Up a Public IPv4 or IPv6 Address

    An ip whois lookup works the same way for IPv4 and IPv6. Paste the address into a web lookup tool, or use the command line:

    • macOS and Linux: whois 8.8.8.8
    • Windows: install a WHOIS client, or use a browser-based RDAP tool
    • Registry web search: enter the address directly into a registry’s search box

    ARIN’s own search auto-detects what you type. Its documentation shows that entering an IPv6 address such as 2001:500:11:: triggers a network query automatically, and that ARIN Whois/RDAP does not accept wildcards in IP or CIDR searches. You can also search a whole CIDR range like 192.0.2.0/24.

    Two practical tips from daily use:

    1. Check that the address is public. Private ranges (10.0.0.0/8, 172.16.0.0/12, 192.168.0.0/16) and CGNAT space return registry placeholder records, which tell you nothing about the device. If you are unsure what your own public address is, confirm it with what is my IP first.
    2. Query IPv6 with the full or compressed form. Both resolve to the same allocation, and IPv6 blocks are far larger, so expect wide ranges such as a /32 assigned to a single provider. The IPv4 vs IPv6 differences explain why those blocks look so big.

    Look Up a Domain and Check Its DNS Records

    A domain whois lookup returns registrar data: creation and expiry dates, the registrar name, status codes, and nameservers. ICANN’s registration data lookup tool covers both domain names and Internet number resources through RDAP.

    Registration data only tells you who manages the name. To see where it points today, resolve the A, AAAA, and MX records, then run a WHOIS lookup on the resulting IPs. That second step reveals the hosting provider or CDN in front of the site.

    For a domain-wide pass, the PacketTools SuperTool runs DNS, MX, SPF, DKIM, DMARC, blacklist, and SSL checks in one go. Pair that with a review of DNS record types if any result looks unfamiliar.

    What Do the Registration Fields Tell You?

    A cybersecurity analyst examines abstract network and location data on computer screens.

    A whois record for an IP describes an organization and its address space, and a domain record describes a name and its registrar. Reading the right fields for each tells you who controls the resource and who to contact about it.

    Read the Organization, IP Range, and Network Contacts

    IP records vary in labeling between registries, but the core fields line up:

    Field (ARIN / RIPE style) What it tells you
    NetRange / inetnum First and last address in the IP block
    CIDR The same IP range in prefix notation
    NetName / netname Short label the holder chose for the network
    Organization / descr The registered holder, showing IP ownership
    OrgAbuseEmail / abuse-mailbox The abuse contact for that range
    RegDate, Updated / created When the record was created and last changed
    Parent / NetType Whether this is a direct allocation or a sub-assignment

    The NetType field deserves attention. A “Direct Allocation” means the registry gave the block straight to that organization. A “Reassigned” or “Reallocated” entry means an ISP or hosting provider carved a smaller block out for a customer, so you may see two nested records.

    The abuse contact is usually the most actionable line. Large providers route those mailboxes into ticketing systems, and a report with timestamps and logs gets handled faster than a vague complaint.

    ARIN states that it publishes only organizational information in its public Whois, including Point of Contact records, and keeps personal profile details confidential. Expect role addresses like noc@ and abuse@, never a named individual’s home address.

    Distinguish Domain Registration Details from IP Records

    Domain records answer a different question. They show the registrar, the creation and expiry dates, status codes such as clientTransferProhibited, and nameserver information that reveals the DNS provider.

    Since GDPR took effect in 2018, registrant names and emails on most domains appear as “REDACTED FOR PRIVACY.” Treat that as normal. The creation date stays visible, and a domain claiming a long history while showing a registration from last month is a strong phishing signal.

    IP records held up better under privacy rules because they describe organizations. One company can hold a single large allocation and run hundreds of domains on it, so a domain’s registrant and the IP’s holder frequently differ.

    Where Does the Data Come From?

    A network researcher examines a visualization of connected servers and data sources.

    IP registration data lives in the whois database of five regional internet registries, which receive address space from IANA and assign it to ISPs and organizations. You can query those databases over the older port 43 protocol or the newer RDAP, and the underlying records are the same.

    Understand the Five Regional Internet Registries

    Each RIR manages internet number resources (IP addresses and ASNs) for its region and sets its own allocation policies:

    RIR Region WHOIS server
    ARIN United States, Canada, parts of the Caribbean whois.arin.net
    RIPE NCC Europe, Middle East, Central Asia whois.ripe.net
    APNIC Asia-Pacific whois.apnic.net
    LACNIC Latin America and the Caribbean whois.lacnic.net
    AFRINIC Africa whois.afrinic.net

    Most web tools follow referrals automatically, so you rarely need to know the right registry in advance. When querying by hand, a result from ARIN that says “transferred to RIPE” or points you elsewhere means you should repeat the query on the listed server.

    Legacy blocks add a wrinkle. Addresses assigned before the RIR system existed, and blocks moved between regions through inter-RIR transfers, can sit in a registry that does not match where the holder operates.

    Compare Traditional WHOIS with RDAP

    WHOIS is a query and response protocol for databases of registered users of resources such as domain names, IP blocks, and autonomous systems. It runs on TCP port 43, defined in RFC 3912, and returns free-form text that varies by registry.

    RDAP (Registration Data Access Protocol, RFC 7480 and related standards) was developed with IETF guidance as its replacement. Key differences:

    Traditional WHOIS RDAP
    Transport TCP port 43 HTTPS
    Output Unstructured text Structured JSON
    Format consistency Differs per registry Standardized fields
    Authentication None Supported
    Referrals Manual or tool-specific Built-in bootstrap and links

    ARIN began building RDAP support after the protocol emerged in 2015, added a web interface in 2019, and made Whois/RDAP its featured service that year while still supporting Whois-RWS. ICANN’s lookup tool also runs on RDAP. For scripts and SIEM enrichment, RDAP’s JSON saves you from writing a parser for every registry’s text layout.

    What Can an IP Lookup Not Prove?

    A registration record identifies the network holder and nothing more. It cannot name the person behind a connection, prove where a device sits, or confirm who sent a specific packet.

    Why the Registered Holder May Not Be the End User

    The organization in the record is whoever the registry assigned the block to. On cloud platforms, that is the provider (AWS, Microsoft, DigitalOcean) even though thousands of customers rent virtual machines on those addresses.

    Residential addresses resolve to the ISP. With carrier-grade NAT, many subscribers share one public IPv4 address at the same moment, and only the ISP’s logs can map a timestamp and port to a subscriber. VPN exit nodes and proxy services produce the same effect: the record names the VPN operator.

    Treat the holder as the party responsible for the network, and the abuse contact as the route to whoever controls the specific machine.

    Why Location, Routing, and Contact Data May Differ

    The country field shows where the holder registered, which frequently differs from where traffic originates. A US company can announce its ARIN block from data centers in Frankfurt or Singapore.

    IP geolocation databases estimate location separately, using routing, latency, and submitted data, so their city-level guesses can disagree with the registry record and with each other.

    Routing is another layer. The autonomous system number (ASN) announcing a prefix in BGP may belong to a different operator than the registered holder, for example when a customer’s block is routed through its upstream provider. Contacts drift too: records with old update dates point to mailboxes nobody reads, so check the “Updated” field before relying on an email address.

    How Can You Use the Results in Network Troubleshooting?

    Registration data works best as one input alongside DNS and path checks. Combined, they tell you what an address is, who to call, and whether the problem sits on your side or theirs.

    Investigate an Unfamiliar Address or Report Abuse

    When an unknown IP shows up in firewall logs or connection tables, work through it in order:

    1. Look up the registration. Note the holder, NetType, and range.
    2. Run reverse DNS. A PTR such as ec2-...compute.amazonaws.com or a hostname with “dsl” or “cable” in it tells you server versus residential quickly.
    3. Check whether your own systems use it. SaaS and Microsoft 365 traffic often hits ranges you do not recognize; the M365 domain checker helps confirm tenant-related DNS.
    4. Report with evidence. Send the abuse contact UTC timestamps, destination ports, and log excerpts. Hosting providers act on specific, reproducible reports.

    If the range is large, block the specific prefix from the record. An IP subnet calculator turns a start and end address into clean CIDR entries for your firewall.

    Correlate Registration Data with DNS and Route Checks

    Mismatches between data sources point to real problems. If a domain’s A record lands on a provider you did not expect, you may be looking at stale DNS, a hijacked record, or an unfinished migration. The DNS propagation checker shows whether resolvers worldwide agree.

    For latency or reachability complaints, run a traceroute and look up the IPs of the hops where delay jumps or replies stop. That identifies which carrier owns the bad segment, and the guide on how to trace a route covers reading those hops. Add a ping test to measure loss before you escalate to that carrier’s NOC.

    Use Registration Data as a Starting Point

    A registration lookup gives you the holder of an IP block, its range, and an abuse contact, pulled from one of five RIRs over WHOIS or RDAP. Domain records add registrar dates and nameservers, though personal registrant details are now mostly redacted.

    Keep the limits in view. The holder may be a cloud provider or ISP far removed from the actual user, the country field reflects registration, and contacts on stale records go unanswered.

    Pair each lookup with reverse DNS, current DNS resolution, and a traceroute before you block a range or file a report. When the record’s “Updated” date is years old, confirm the contact through the provider’s own abuse page before sending evidence.

  • DNS Leak Test: How to Check and Fix Exposed DNS

    DNS Leak Test: How to Check and Fix Exposed DNS

    You run a DNS leak test to answer one question: which DNS resolver handles your lookups when your VPN, secure DNS, or filtering setup is active? If the test shows your ISP’s resolver while you expect your VPN provider’s, your DNS is taking a path you didn’t choose. That path tells someone else which domains you visit.

    A laptop displays a network privacy check with connected servers and a shield icon.

    To check for exposed DNS, first record your normal resolver with the VPN off. Then run a resolver-aware dns leak test with the VPN or secure DNS on, and confirm that every listed resolver belongs to the operator you intended. Any resolver owned by your ISP or local network during a protected session is a leak. Distant servers or multiple servers from your chosen provider are normal.

    PacketTools builds its free, no-login diagnostics around this kind of verification. They come from nearly three decades of production network work, and they log no IPs, queries, or test data. DNS privacy comes down to evidence. With a few controlled tests, you can tell whether a strange resolver is a real exposure or ordinary anycast routing.

    What Counts as a DNS Leak?

    A cybersecurity analyst examines network traffic as data packets escape a protected connection.

    A DNS leak happens when your DNS queries go to a resolver outside the path you configured. The most common case is your ISP’s resolver answering while a VPN is connected. Whether a given resolver counts as a leak depends on what you intended, which is why the definition starts with your setup.

    How Do DNS Queries Reach a Resolver?

    The domain name system translates names like packettools.com into an IP address before any page content loads. Your device sends that lookup to a recursive DNS resolver. The resolver then asks the authoritative servers for the answer.

    Your operating system picks the resolver from one of several places:

    • DHCP: Your router or ISP hands out resolver addresses automatically.
    • Manual configuration: You set the resolvers yourself on the network adapter.
    • VPN client: The client pushes its own DNS servers when the tunnel comes up.
    • Browser secure DNS: Chrome, Edge, or Firefox can send DNS-over-HTTPS queries straight to a provider and skip the OS resolver.

    A leak test works from the far end of this chain. Your browser looks up unique, never-cached hostnames. The test operator’s authoritative server then records which resolver came asking. You see the resolver’s address and owner. You never see your device’s address in that list.

    When Is an Unexpected Resolver Actually a Leak?

    An unfamiliar resolver is a leak only when it breaks your intended path. Use this rule set:

    Your setup Resolver shown Verdict
    VPN connected VPN provider’s DNS No leak
    VPN connected Your ISP’s DNS Leak
    VPN connected Google or Cloudflare via browser DoH Bypass of the VPN, encrypted, a policy decision
    No VPN, custom DNS Your chosen provider Working as configured
    No VPN, custom DNS Mixed ISP and chosen provider Partial leak

    Your threat model settles the bypass case. If you want only your VPN provider to see lookups, browser DoH to a third party breaks that goal. If your goal is hiding lookups from your ISP, encrypted DoH meets it.

    What Can Exposed DNS Queries Reveal?

    HTTPS hides page content, but plaintext DNS exposes every hostname you resolve. That includes banking portals, health sites, internal SaaS tenants, and the update servers your software calls home to. Taken together, those lookups add up to a detailed record of your browsing history.

    Whoever runs the resolver sees this data, and so does anyone on the unencrypted path. On public Wi-Fi, that can include the hotspot operator. For admins, leaked lookups for internal hostnames also reveal tooling and vendor relationships.

    How Are DNS Leaks Different from IP and WebRTC Leaks?

    Each leak exposes something different, so each needs its own test:

    • DNS leak: reveals which domains you look up to the resolver’s operator.
    • IP leak: reveals your real public address to the sites you visit. You can confirm your visible address with a quick check of your IP address.
    • WebRTC leak: the browser’s real-time media APIs expose local or public IP addresses through STUN requests, even when a VPN is up.

    A clean DNS result says nothing about WebRTC leaks, and a clean WebRTC result says nothing about DNS. Run both checks whenever you validate a VPN.

    How Do You Run a Reliable Check?

    A reliable check compares a recorded baseline against a protected run, then repeats that comparison across browsers, address families, and networks. A single test from a single tab misses fallback resolvers and browser overrides, and those are where most leaks hide.

    Record Your Public IP and Expected DNS Provider

    Start with the VPN disconnected and any custom secure DNS turned off. Write down two things:

    1. Your public IPv4 address, plus the IPv6 address if you have one. The IP address basics guide explains which one sites see.
    2. The organization names behind the DNS servers that appear. These usually belong to your ISP, or to a hotel or office network.

    You don’t need every resolver IP. What you need is the operator names that handle your DNS when nothing protects it. Those names become your leak signature, and seeing any of them later means traffic escaped. A screenshot works fine as a record.

    Run the Test with Your VPN or Secure DNS Enabled

    Connect the VPN and wait until the client reports a full connection. Turn on the kill switch if the client has one. Then flush the local cache so earlier answers don’t skew the run:

    • Windows: ipconfig /flushdns
    • macOS: sudo dscacheutil -flushcache; sudo killall -HUP mDNSResponder
    • Linux with systemd-resolved: sudo resolvectl flush-caches

    Run the extended mode on dnsleaktest.com, or let browserleaks.com run its automatic DNS check. Extended tests send several rounds of probes, so secondary and fallback resolvers have a chance to show up. A single round can miss them.

    Repeat the Check Across Browsers and Networks

    One browser can follow different DNS rules from another on the same machine. Run the test in at least two:

    • One browser with secure DNS enabled
    • One browser with secure DNS disabled

    Then repeat on a second network, such as a phone hotspot. Test again right after the VPN reconnects and after waking the laptop from sleep. Leaks often show up during transitions and disappear on a steady connection. If your network has IPv6, confirm the test reports both IPv4 and IPv6 results, because an IPv6 path can skip a tunnel built only for IPv4.

    How Do You Interpret the Resolver Results?

    A cybersecurity analyst reviews a network diagnostics display at a workstation.

    You interpret results by checking who operates each listed resolver against the operator you intended. Resolver location and resolver count carry much less weight than ownership, and a browser test has blind spots you should know about before calling a setup clean.

    Compare Resolver Operators with Your Intended Setup

    Look at the organization or ASN column first. Then sort every resolver into one of these groups:

    • Expected: your VPN provider, or the encrypted DNS service you chose. This is a pass.
    • Your baseline ISP: any match with the operator names from your unprotected run means ISP DNS is still handling queries. This is a leak.
    • Third-party DNS server you didn’t pick: Google DNS or Cloudflare showing up with a VPN active usually points to browser DoH or a manual adapter setting. Trace it before you accept it.

    The resolver IP doesn’t need to match the exit IP your VPN gave you. Many providers run DNS on separate infrastructure from their gateways, so a mismatch between those two addresses is normal.

    Why Multiple or Distant DNS Servers May Be Normal

    Large resolvers use anycast and pools of backend nodes. Several probes in one test can land on several different servers that all belong to the same operator. Ten Google addresses means one provider, so treat that as a single result.

    Geography misleads the same way. A US user on Cloudflare might see a resolver in another state, or in another country during peering shifts. Distance tells you about routing. Ownership tells you about privacy. If timing looks off, a ping test or a traceroute to the resolver shows where the latency comes from.

    What a Browser-Based Test Cannot Prove

    A browser test only sees what the browser resolves. Its limits:

    • DNS over TLS (DoT) runs at the system level on port 853, and a web page can’t detect it.
    • Encryption labels in many tools reflect whether a provider supports encrypted DNS. They don’t confirm your connection uses DNS-over-HTTPS (DoH) or DoT. Cloudflare queried over plaintext port 53 still gets labeled “encrypted.”
    • Apps, games, and background services can resolve through other paths the page never sees.
    • A result showing no resolvers at all often means browser DoH, aggressive security software, or caching blocked the probes.

    To confirm DNS traffic outside the browser, capture packets with Wireshark. Unencrypted queries to non-tunnel interfaces show up immediately.

    Why Does DNS Bypass the Intended Path?

    DNS bypasses your intended path when some layer (the OS, router, browser, or VPN client) applies its own resolver choice after your configuration takes effect. The causes fall into three groups: how the tunnel claims DNS, where settings compete, and what happens during network changes.

    How VPN Tunnels and DNS Resolver Choices Interact

    A VPN client protects DNS when it does two things. It pushes its own resolvers, and it blocks DNS sent anywhere else. That blocking is what clients call DNS leak protection. Without it, the OS can still reach the original resolver through the physical adapter.

    Manual OpenVPN or WireGuard profiles cause this often. If the config omits a DNS line, or the OS ignores it, the tunnel carries your traffic while DNS keeps going to the router. Split tunneling makes it worse: excluded apps, or a browser on the exclusion list, resolve outside the tunnel by design. A general DNS troubleshooting walkthrough helps you confirm which interface owns DNS.

    Where Device, Router, and Browser Settings Conflict

    Each layer can override the one below it:

    • Router DHCP pushes ISP DNS to every client. Your laptop might be correct while the TV and phones leak. Check the DNS fields in your router’s admin interface.
    • Manual DNS setup on the adapter competes with resolvers the VPN pushes.
    • Smart Multi-Homed Name Resolution in Windows sends queries out every interface in parallel and takes the fastest answer. That behavior hands lookups to the ISP resolver while the VPN is up.
    • Browser DoH skips the OS resolver entirely and sends queries to the browser’s chosen provider.

    When IPv6, Reconnection Gaps, or Software Change the Route

    An IPv6 leak happens when the tunnel carries only IPv4 while your ISP provides working IPv6. Your device prefers IPv6 and sends DNS outside the tunnel. The IPv4 vs IPv6 comparison explains why dual-stack systems choose v6 first.

    Reconnection gaps cause leaks that come and go. When a laptop wakes or switches Wi-Fi, the OS restores the default resolver before the tunnel comes back. Software causes the rest: updates that reset DNS settings, and malware that rewrites resolvers to send you to phishing servers.

    How Do You Fix and Prevent Unintended DNS Routing?

    Fix DNS routing one layer at a time, and retest after each change so you know which fix closed the leak. Start with the VPN and the OS, isolate the browser and IPv6 next, and then add encryption and network-level controls.

    Correct VPN and System DNS Settings, Then Retest

    Here is how to fix a DNS leak at the base layer:

    1. Use the provider’s official client in place of a hand-built profile whenever one exists.
    2. Turn on DNS leak protection and the kill switch, and never turn either off.
    3. Set the physical adapter’s DNS back to automatic so it can’t compete with the tunnel’s resolvers.
    4. Take your browser off any split-tunnel exclusion list, or disable split tunneling.
    5. On Windows, disable Smart Multi-Homed Name Resolution through Group Policy (“Turn off smart multi-homed name resolution”).
    6. Update or reinstall the client. Older versions mishandle network changes.

    Flush the DNS cache, reconnect, and run the extended test again. Change one variable per run. If lookups start failing after a change, the DNS lookup failed and DNS server not responding guides cover the common breakages.

    Check Browser Secure DNS and IPv6 Separately

    Browser secure DNS gets its own decision. To keep all lookups inside the VPN, turn it off:

    • Chrome: Settings → Privacy and security → Security → Use secure DNS
    • Firefox: Settings → General → Network Settings → Enable DNS over HTTPS

    If you’re comfortable with your DNS provider handling queries in place of your VPN, keeping DoH on is a valid choice.

    For IPv6, turn on the client’s IPv6 leak protection. If the VPN can’t tunnel v6, disable IPv6 on the active adapter, then test IPv4 and IPv6 again separately.

    Use Encrypted DNS and Network Controls Where Appropriate

    How you prevent DNS leaks without a VPN depends on encryption plus enforcement. Configure DNS over HTTPS (DoH) or DNS over TLS (DoT) at the OS or router so lookups leave the device encrypted. That stops on-path snooping and DNS spoofing, and it blunts man-in-the-middle attacks on public Wi-Fi.

    On networks you manage, block outbound port 53 to everything except your approved resolvers, and allow port 853 only to your DoT provider. Devices that hardcode resolvers then fail closed and can’t leak. The same rule cuts off malware that redirects DNS to phishing infrastructure. Confirm the firewall rule with an open port checker and a fresh resolver test.

    Verify That DNS Uses the Resolver You Chose

    DNS privacy holds only when the resolver in your test results matches the one you configured, every time you check. Record a baseline with protection off. Run extended tests with protection on, and judge each resolver by its operator. Location and resolver count tell you little.

    ISP resolvers during a VPN session are a leak. Several nodes from your chosen provider are normal, and browser DoH to a third party is a policy choice you make on purpose. When results look wrong, fix one layer at a time: VPN client, adapter, browser, IPv6, then network enforcement.

    Repeat the check after client updates, Wi-Fi changes, and wake-from-sleep, because transitions are when DNS falls back to the default resolver. Keep the baseline screenshot from your unprotected run, since spotting any of those operator names later is the fastest way to catch an exposed DNS resolver.

  • Open Port Checker: Test Reachability and Troubleshoot Results

    An open port checker tells you whether a specific TCP port on your public IP address or hostname accepts connections from the internet. To check whether a port is open, run an external test against your public IP or hostname and the exact port number, then read the result: open means a TCP handshake completed, closed means the host refused, and filtered or timed out means something on the path dropped the attempt. That one result separates “my service is down” from “my firewall or router is in the way.”

    A cybersecurity analyst checks network connections on a laptop.

    The catch is that a port test from inside your own network can pass while outside visitors still can’t connect. NAT loopback, host firewalls, cloud security groups, and carrier-grade NAT all change what the outside world sees.

    PacketTools builds its browser-based diagnostics from nearly three decades of production IT work, and the open port checker follows the same rules as the rest of the site: no sign-in, no tracking, and no IPs, queries, or test data logged or stored. Once you know how to read open, closed, and filtered results, you can tell which layer to fix and stop changing router settings at random.

    How Do You Check Whether a Port Is Open?

    You check a port by pointing an external tester at the exact public address and port number a remote client would use. Getting the target right (public IP or the hostname clients resolve) and testing from outside your LAN accounts for most of the accuracy.

    Choose the Public IP Address or Hostname and Port

    Start with the address the internet sees. Your PC’s 192.168.x.x or 10.x.x.x address is private and unreachable from outside, so a port checker needs your public IP address. You can check your IP address to get the value your router presents to the world.

    If clients connect by domain name, test the hostname too. That adds DNS to the check: if the hostname resolves to an old IP, you’ll be testing the wrong machine. A quick DNS propagation checker run confirms the A or AAAA record points where you expect.

    Pick the port deliberately:

    • The port clients connect to, which may differ from the internal port if your router maps 8443 externally to 443 internally.
    • The right protocol. Most online port testing is TCP. UDP services need a different approach (covered below).
    • The right address family. An IPv6 address bypasses NAT entirely, so an IPv6 test may succeed while IPv4 fails, or the reverse. The IPv4 vs IPv6 differences explain why the two paths behave so differently.

    Run a Safe Browser-Based Check from Outside Your Network

    A browser-based online port checker sends one TCP connection attempt from a server on the internet to your target. That external vantage point is the whole value: it walks the same path a real visitor takes, through your ISP, router, and firewalls.

    A clean workflow looks like this:

    1. Confirm the service is running locally first.
    2. Enter your public IP or hostname and a single port.
    3. Run the open port check and note open, closed, or filtered.
    4. Change one thing (a firewall rule, a forward), then retest the same port.

    Avoid testing from a device on the same LAN through your own public IP. Many routers loop that traffic back internally, so the result says nothing about outside reachability. If you need a second outside view, use a phone on cellular data.

    PacketTools’ open port checker runs these tests in real time without storing the target or the result, which suits checks against production hosts you’d rather not leave in someone’s logs. It sits alongside the ping test and other network tools on the site.

    What Do Open, Closed, and Filtered Results Mean?

    A network analyst examines a visualization showing three different connection pathways.

    Each port status describes what happened to the connection attempt, and only “open” confirms service availability. Closed proves the host is reachable but idle on that port; filtered proves only that no answer came back, and UDP results carry even less certainty.

    Result What came back What it tells you
    Open SYN-ACK, handshake completed A service is listening and reachable from the test location
    Closed TCP RST (refusal) Host is reachable, nothing listens on that port
    Filtered / timeout Nothing, or an ICMP prohibited message A firewall, router, or broken path dropped the attempt

    What a TCP Connection Can Confirm

    TCP is connection-oriented, so a successful handshake is hard evidence. When the checker gets a SYN-ACK, some process accepted the connection on that port, from that vantage point, at that moment.

    It does not confirm the right application answered. A reverse proxy, a default web page, or a leftover service can hold the port. If port 443 shows open but your site still fails, test the application layer next: TLS certificate, HTTP response, and logs.

    Results are also location-relative. The Nmap reference guide notes that a scan from the same network may show a port as open while the same port shows filtered from across the internet at the same time. Port state belongs to the path, not the port itself.

    Why a Timeout Does Not Prove a Port Is Closed

    A timeout means silence, and silence has several causes. A firewall rule set to drop packets, a host that is powered off, a missing port forward, or a routing problem all look identical to a single external probe.

    Dropping is the normal behavior for well-configured firewalls, because it gives scanners nothing to work with. So a filtered result on a port you never meant to expose is good news. On a port you need open, it points you at filtering somewhere between the tester and the service.

    To narrow it down, confirm the host answers at all (ping, if ICMP is allowed, or a known-open port like 443), then use how to trace a route techniques to see where the path stops.

    Why UDP Needs a Different Test

    UDP has no handshake. Send a packet to an open UDP port and the service may ignore it unless the payload matches its protocol. Send one to a closed UDP port and the host might return an ICMP port-unreachable, or a firewall might drop that reply.

    That leaves most UDP checks with two outcomes: “closed” when an ICMP error arrives, and “open or filtered” when nothing does. Nmap labels this state open|filtered for exactly that reason. For DNS, game servers, VoIP, or WireGuard, test with a protocol-aware client (a DNS query with dig, the game client itself, a VPN handshake) and treat silence as inconclusive.

    Why Is a Port Unreachable When the Service Is Running?

    A running service is unreachable when something between the socket and the internet blocks or misroutes the connection. Work outward from the server: bind address and host firewall first, then the router or cloud edge, then your ISP’s network.

    Check the Listening Service and Host Firewall

    Confirm the process listens on the right interface. On Linux, ss -tlnp lists TCP listeners with their owning process; on Windows, netstat -ano | findstr LISTENING does the same.

    Read the local address column carefully:

    • 0.0.0.0:8080 or [::]:8080 means all interfaces, which is what you want for external access.
    • 127.0.0.1:8080 means localhost only. No firewall change will fix this; edit the server configuration to bind to the LAN address or all interfaces.

    Next, test from another machine on the same private LAN with netcat: nc -zv 192.168.1.50 8080. Success here proves the service and host firewall pass LAN traffic.

    If the LAN test fails, inspect the host firewall. On Ubuntu, sudo ufw status verbose shows allowed ports; sudo iptables -L -n -v reveals raw rules and drop counters. Windows Defender Firewall rules are profile-specific, so a rule scoped to “Private” won’t help when the adapter is classified as “Public.”

    Trace Port Forwarding, NAT, and Cloud Rules

    At home or in a small office, NAT hides your LAN behind one public IP. Port forwarding settings tell the router which internal host receives traffic for a given external port. Common mistakes in a port forwarding test:

    • The forward points to an old internal IP after DHCP reassigned the server. Use a DHCP reservation.
    • The rule covers UDP when the service needs TCP, or the reverse.
    • External and internal ports are mismatched.
    • Double NAT: an ISP modem routes in front of your own router, so the forward on the inner router never sees traffic. Log into your router IP address and compare the WAN address with your public IP.

    In the cloud, the equivalent layers are security groups and network ACLs. An AWS security group, Azure NSG, or GCP firewall rule must allow inbound traffic on the port from the right source range, and the instance’s own OS firewall still applies on top.

    Rule Out CGNAT, VPN Routing, and ISP Filtering

    If your router’s WAN address falls in 100.64.0.0/10 or doesn’t match your public IP, you’re behind carrier-grade NAT. CGNAT means inbound connections stop at your ISP’s NAT, and no router setting can forward them. Your options are an IPv6 path, a static public IP from the ISP, or a tunnel to a host with a public address.

    A VPN client on the server changes routing too. Return traffic may leave through the tunnel, so the remote client sees replies from the wrong IP and drops them. Split tunneling or policy routing fixes that.

    ISP filtering is the last suspect. Residential providers commonly block inbound port 80 and outbound or inbound port 25. If every other layer checks out, run the service on an alternate port such as 8080 and retest; a success there points at the provider. The broader network troubleshooting guidance on PacketTools covers isolating ISP-side faults.

    Which Ports Should You Test?

    An IT professional checks network connections on a computer beside a router.

    Test the ports your public services need, plus the ones that should stay closed. Well-known server ports run from 0 to 1023, and application ports sit above that, often on defaults that attackers scan for constantly.

    Common Web, DNS, Mail, and Remote-Access Ports

    These are the common ports you’ll verify most:

    Port Protocol Service Should it face the internet?
    80 TCP HTTP Yes for web servers, mainly to redirect to HTTPS
    443 TCP HTTPS Yes for web servers
    53 TCP/UDP DNS Only on authoritative or intended public resolvers
    25 TCP SMTP (server-to-server mail) Yes on mail servers only
    587 / 465 TCP Mail submission Yes when clients send through your server
    22 TCP SSH Restrict by source IP or put behind a VPN
    3389 TCP RDP No; use a VPN or gateway
    21 TCP FTP Rarely; prefer SFTP over port 22
    23 TCP Telnet No, it sends credentials in clear text
    445 TCP SMB No

    If SMTP looks broken, check port 25 first, both inbound to your server and outbound from it, since many residential and cloud networks restrict it. PacketTools’ Email Health and SuperTool checks cover the DNS side of mail (MX, SPF, DKIM, DMARC) once the port answers.

    Application, Database, Game, and P2P Ports

    Databases are the ports you most want to see filtered from outside:

    • MySQL / MariaDB: 3306
    • PostgreSQL: 5432
    • Redis: 6379
    • MongoDB: 27017

    An open result on any of these from the public internet usually means a bind address of 0.0.0.0 plus a permissive firewall or security group. Redis and MongoDB in particular have a long history of exposed instances with weak or no authentication.

    Application ports vary by product. Alternate web ports 8080 and 8443 are common for admin panels and dev servers, and those panels deserve the same scrutiny as databases.

    Game ports and P2P ports are the classic port forwarding cases. A Minecraft Java server defaults to TCP 25565; Plex uses 32400; torrent clients let you choose a port. Use the exact number configured in the application, and remember that many game servers also need UDP, which a TCP-only check won’t confirm.

    How Can You Test Ports Responsibly?

    Responsible port testing means checking only systems you control or have written permission to test, and treating a reachability result as one input to network security. A single connection attempt is ordinary traffic; sweeping thousands of ports on someone else’s hosts is reconnaissance.

    Check Only Systems You Own or Are Authorized to Test

    A one-port check against your own server is the same as a browser visit. A port scanner that sweeps ranges is different. By default, nmap <target> probes 1,000 TCP ports on the host, and running that against networks you don’t own can breach acceptable-use policies, trigger abuse reports, and in some jurisdictions create legal exposure.

    Practical boundaries:

    • Scan your own public IPs, domains, and cloud instances freely.
    • For client or employer networks, get scope in writing: IP ranges, time windows, and allowed tools.
    • Many cloud providers publish penetration testing policies; read them before running a network scanner against hosted assets, even your own.
    • On shared hosting, your IP may front other customers. Test your port, not the whole address range.

    A single-port checker fits verification work: “did my forward work?” Full port scanning with nmap fits audits, where you need an inventory of open ports and have authority to collect it. Keep the two jobs separate. An IP scanner on your own LAN helps with inventory before you expose anything.

    Use Local and External Checks Without Mistaking Reachability for Security

    Run both views. Local checks (ss, netstat, netcat from a LAN host) tell you what the server offers. External checks tell you what the internet can reach. A gap between the two shows which layer filters traffic.

    An open result answers “can I connect?” and nothing more. Port 443 open on a web server is the goal. Port 3306 open to the world is an incident waiting to happen, even with a strong password.

    After every external test, ask three things:

    • Does this port need to be public at all?
    • Can access be limited by source IP, VPN, or an identity-aware proxy?
    • Is the service behind it patched and authenticated?

    Retest ports you closed on purpose. A filtered result on RDP or a database from outside confirms the block works. More hardening material lives in the cybersecurity section.

    Confirm the Path, Then Fix the Right Layer

    A port check is most useful when you read it as evidence about a path. Open means a TCP handshake completed from that location. Closed means the host answered with a refusal. Filtered means silence, which could be a firewall, a missing forward, a dead host, or a broken route.

    When a service runs but the port won’t open, work outward in order:

    1. Bind address and listener (ss, netstat)
    2. Host firewall (ufw, iptables, Windows Defender Firewall)
    3. Router port forwarding, NAT, or cloud security groups
    4. CGNAT, VPN routing, and ISP filtering

    Treat UDP silence as inconclusive and verify with a protocol-aware client. Keep databases, RDP, SMB, and Telnet filtered from the internet, and limit scanning to systems you’re authorized to test. After each change, retest the single port from outside your network and compare the new result with the last one.

  • IPv4 vs. IPv6: Key Differences and Compatibility

    IPv4 vs. IPv6: Key Differences and Compatibility

    Every device that talks across a network needs an IP address, and the Internet Protocol (IP) now comes in two versions that run side by side. IPv4 uses 32-bit addresses and leans on NAT to stretch a nearly exhausted pool, while IPv6 uses 128-bit addresses, autoconfigures hosts, and restores direct end-to-end reachability. For any network you run today, the practical answer is dual-stack: keep IPv4 working and enable IPv6 alongside it, because the two protocols cannot talk to each other natively.

    Two network routers connect through glowing data nodes in a server room.

    That lack of native compatibility drives most of the real-world pain in the ipv4 vs ipv6 question. A site can look fine over one protocol and fail silently over the other, a VPN can protect your IPv4 traffic while IPv6 slips out untouched, and a DNS record can point clients at a path nobody tested.

    PacketTools was built by an engineer with more than 28 years in enterprise networking, and the same browser-based diagnostics on the site are used in production to verify VPNs and analyze routing. By the end, you will know which differences change your configuration, how the two stacks coexist, and how to test both without guessing.

    How Do the Protocols Compare at a Glance?

    A network router connects two contrasting streams of data across a digital network.

    IPv6 changes the address format, the way hosts get configured, and the structure of the header that every router reads, while keeping the same job of carrying data packets from source to destination. The address size gets the headlines, but header and configuration changes are what you feel in day-to-day operations.

    Criteria IPv4 IPv6
    Address length 32-bit 128-bit
    Total addresses About 4.3 billion About 3.4 × 10^38
    Notation Dotted decimal (192.0.2.10) Hex with colons (2001:db8::1)
    Header size 20 to 60 bytes, variable 40 bytes, fixed
    Host configuration Manual or DHCP SLAAC, DHCPv6, or manual
    NAT needed for scale Yes, in most networks No

    Address Size, Notation, and Available Space

    A 32-bit address gives you 2^32, or roughly 4.3 billion, possible values. A 128-bit address gives you about 3.4 × 10^38 unique addresses, a number large enough that scarcity stops being a design constraint.

    You write an IPv4 address as four decimal octets from 0 to 255, such as 203.0.113.45. An IPv6 address is eight groups of four hex digits, such as 2001:0db8:0000:0000:0000:0000:0000:0001. Two shortening rules apply: drop leading zeros in each group, and replace one run of all-zero groups with ::, giving 2001:db8::1.

    Subnetting shifts too. In IPv4 you carve the address space carefully with CIDR, counting every host; an IP subnet calculator saves you from arithmetic mistakes on a /27 or /29. In IPv6, a LAN segment gets a /64 almost by default, and you plan prefixes by site or function instead of squeezing host counts.

    Configuration, Packet Handling, and Compatibility

    IPv4 hosts get their settings from DHCP or manual entry. IPv6 hosts can build their own address from a router advertisement through SLAAC, which means a device can come online with a global address before you have touched a DHCP scope.

    The IPv4 header carries a checksum and options that make its length vary. IPv6 drops the header checksum, moves options into extension headers, and fixes the base header at 40 bytes, so routers process it with less work per packet.

    The most important practical difference is that an IPv4-only host and an IPv6-only host cannot exchange packets directly. Oracle’s IPv6 administration guide lays out an interoperability matrix where an IPv6-only client and an IPv4-only server simply fail to connect. Anything bridging them needs dual-stack hosts or a translation layer.

    Why Does IPv4 Still Depend on NAT?

    Several household devices connect through one router to the internet.

    IPv4 depends on NAT because there are far more connected devices than public IPv4 addresses, and the free pool is gone. Network address translation lets dozens of hosts share one public address, at the cost of direct reachability.

    IPv4 Exhaustion and the Growth of Connected Devices

    The Internet Assigned Numbers Authority handed out its last IPv4 blocks in 2011. The regional internet registries (ARIN for North America, RIPE NCC for Europe, APNIC for Asia-Pacific, plus LACNIC and AFRINIC) then worked through their own pools until they hit exhaustion as well.

    Today, organizations that need more IPv4 space buy it on secondary markets, where prices have sometimes exceeded $50 per address. That cost lands on hosting bills and cloud invoices, especially for anything that needs a dedicated public IP.

    Device growth makes the gap worse every year. A typical home now holds phones, laptops, TVs, cameras, thermostats, and voice assistants, and Internet of Things (IoT) deployments in offices and factories add hundreds more endpoints per site. Compare that with a residential IPv6 allocation of a /64, which alone contains about 18 quintillion addresses.

    What NAT Solves, and What It Complicates

    NAT rewrites the private source address of outbound traffic (from ranges like 10.0.0.0/8, 172.16.0.0/12, and 192.168.0.0/16) to your router’s public address, tracking each session by port. Your router IP address on the LAN side is one of those private addresses; the public one is what remote servers see.

    The trade-off is end-to-end connectivity. Hosts behind NAT can start outbound connections, but unsolicited inbound traffic has nowhere to go unless you configure port forwarding. In practice, that breaks or degrades:

    • Self-hosted services such as a home lab, game server, or remote desktop
    • VoIP and video calls, which fall back to relay servers using STUN and TURN
    • Peer-to-peer tools that need both sides to accept connections
    • IoT devices that end up relying on cloud relays for remote access

    Carrier-grade NAT stacks a second translation layer at your ISP. If your WAN interface shows an address in 100.64.0.0/10, you are behind CGNAT, and port forwarding on your own router will not expose anything to the internet. IPv6 sidesteps all of this because each host gets a globally routable address, and you control access with firewall rules instead of address translation.

    What Changes in Network Setup, Routing, and Security?

    Enabling IPv6 changes how hosts receive addresses, which traffic types exist on your segments, and where packet fragmentation happens. Your firewall policy and monitoring need updates too, because IPv6 hosts become reachable in ways IPv4 hosts behind NAT never were.

    Address Assignment with DHCP, SLAAC, and DHCPv6

    In IPv4, DHCP hands out an address, mask, gateway, and DNS servers. When it fails, Windows and macOS fall back to a 169.254.x.x link-local address, which is the classic sign of a dead DHCP server or a broken relay.

    IPv6 gives you three options:

    1. SLAAC: routers advertise a prefix, and hosts generate their own interface ID. Many clients add temporary privacy addresses that rotate.
    2. Stateless DHCPv6: SLAAC builds the address while DHCPv6 supplies extras like DNS servers.
    3. Stateful DHCPv6: the server assigns addresses and keeps lease records, closer to the IPv4 model.

    One detail catches people: Android does not support stateful DHCPv6, so a network that relies only on DHCPv6 leaves Android devices without a global IPv6 address. Advertise DNS through router advertisements (RDNSS) as well. Also note that the default gateway in IPv6 comes from router advertisements, never from DHCPv6.

    Unicast, Multicast, Anycast, and Broadcast Traffic

    IPv4 supports unicast, multicast, and broadcast. IPv6 removes broadcast entirely and relies on multicast for jobs like neighbor discovery, which replaces ARP.

    That has a direct troubleshooting impact. If you filter ICMPv6 aggressively on switches or host firewalls, neighbor discovery and router advertisements stop working, and IPv6 breaks in ways that look random. Allow the core ICMPv6 types (router solicitation and advertisement, neighbor solicitation and advertisement, packet too big).

    An anycast address is a single address announced from multiple locations, with routing protocols steering clients to the nearest instance. Large DNS resolvers and CDNs use it heavily on both protocols. IPv6 formalizes it as an address type, while IPv4 achieves the same effect through BGP announcements.

    Headers, Fragmentation, QoS, and IPsec in Practice

    IPv4 routers can fragment packets in transit. IPv6 routers never fragment; only the sending host does, using path MTU discovery driven by ICMPv6 “Packet Too Big” messages. Block those messages and you get the familiar symptom of a site where small pages load and large transfers hang.

    For quality of service (QoS), IPv6 carries a Traffic Class field equivalent to IPv4’s DSCP marking, plus a 20-bit Flow Label for identifying flows. Your existing QoS policy translates with minor syntax changes.

    IPsec, or Internet Protocol Security, was mandatory in early IPv6 specifications and was later downgraded to recommended. It runs equally well on IPv4. IPv6 traffic is not encrypted by default, so treat claims of “built-in security” with care and keep your firewall rules at parity across both stacks. Our cybersecurity coverage goes deeper on hardening.

    How Can IPv4 and IPv6 Work Together?

    IPv4 and IPv6 coexist through three mechanisms: dual-stack, translation, and tunneling. Most ISPs, cloud providers, and enterprises combine them, with dual-stack as the default and translation reserved for IPv6-only segments that still need IPv4 content.

    When Is Dual-Stack the Practical Choice?

    Dual-stack means every interface carries both an IPv4 and an IPv6 address, and both are routed natively. When DNS returns an A and an AAAA record, modern clients try IPv6 first and fall back to IPv4 within a few hundred milliseconds using the Happy Eyeballs algorithm.

    Choose dual-stack when you still run IPv4-only applications, partners, or appliances, which describes nearly every enterprise network. Its weakness is operational: you maintain two address plans, two sets of ACLs, and two routing tables. The most common mistake in a dual-stack network is hardening IPv4 carefully while leaving IPv6 wide open because “nobody uses it yet.”

    Where Do NAT64, DNS64, and Tunneling Fit?

    NAT64 with DNS64 lets IPv6-only clients reach IPv4-only servers. DNS64 synthesizes an AAAA record from the server’s A record using a special prefix (commonly 64:ff9b::/96), and the NAT64 gateway translates those packets to IPv4. Mobile carriers use this widely on IPv6-only networks, and the approach suits new data center segments where you want to stop allocating IPv4.

    Tunneling wraps IPv6 packets inside IPv4 headers so they can cross an IPv4-only path. It is useful for labs or for connecting islands of IPv6, though it adds MTU overhead and creates paths your firewall may not inspect. Disable automatic tunneling protocols like 6to4 and Teredo on endpoints unless you depend on them.

    Mechanism Best fit Main caution
    Dual-stack Mixed enterprise and hosting networks Two policies to keep in sync
    NAT64/DNS64 IPv6-only clients reaching IPv4 content Breaks apps with hard-coded IPv4 literals
    Tunneling Crossing IPv4-only transit MTU issues and uninspected paths

    What Should You Check Before an IPv6 Migration?

    Start with an inventory, then fix the systems that can stall the rollout. Before you enable IPv6 on user segments, confirm:

    • ISP support: does your provider delegate a prefix, and what size? A /48 or /56 gives you room to subnet.
    • Firewalls and VPN concentrators: both must enforce the same policy and logging over IPv6.
    • DNS: you need AAAA records for published services and reverse zones for logging.
    • Monitoring and SIEM: check that they parse and store IPv6 addresses cleanly.
    • Applications: look for hard-coded IPv4 literals and address fields sized for 15 characters.
    • Management access: test SSH and admin interfaces over IPv6 before you depend on them.

    Roll out in phases: core and distribution first, then servers, then user access. IPv6 adoption reached roughly 45% of global traffic in 2025, so a meaningful share of your visitors already arrives over IPv6 if your services allow it.

    How Do You Test and Troubleshoot Both Protocols?

    Test each protocol separately, because a dual-stack host hides failures: when IPv6 breaks, Happy Eyeballs falls back to IPv4 and the problem goes unnoticed until something depends on it.

    Confirm Public Addresses and DNS Records

    Begin by confirming which public addresses you present. A what is my IP check shows your current public IP addresses; if you see only IPv4 on a network that should be dual-stack, the issue sits at the router, the ISP delegation, or a VPN client. If you are new to address types, our IP address basics guide covers public versus private ranges.

    Next, compare A and AAAA records for your service. A stale or wrong AAAA record is one of the most common dual-stack faults, since IPv6 clients try it first. Run a DNS lookup for both record types, and after changes, use a DNS propagation checker to confirm resolvers worldwide return the new IPv6 addresses. When lookups fail entirely, the steps to troubleshoot DNS issues apply to both record types.

    Compare Connectivity and Network Paths

    Ping each protocol explicitly. On Windows, use ping -4 host and ping -6 host; on Linux and macOS, use ping and ping6 (or ping -6). A browser-based ping test gives you an outside view of reachability.

    IPv4 and IPv6 traffic frequently take different routes, with different peering and different latency. Run traceroute over each protocol (tracert -6 or traceroute -6) and compare hops; the guide on how to trace a route explains reading the output. Watch for:

    • IPv6 latency much higher than IPv4, which points to poor peering or a tunnel in the path
    • Large transfers stalling over IPv6 only, which points to blocked ICMPv6 “Packet Too Big”
    • Ping by IP working while ping by name fails, which points to DNS

    Wireshark hosts a simple IPv4 and IPv6 connectivity test that loads images from IPv4-only and IPv6-only locations, a quick way to see whether each stack works end to end in a browser.

    Check TLS Reachability and VPN IPv6 Leaks

    TLS certificates and listeners must work on both stacks. A web server that binds only to 0.0.0.0 listens on IPv4 alone, so IPv6 clients hit a timeout or the wrong virtual host. Test your SSL/TLS endpoint by connecting to the IPv6 address directly (openssl s_client -connect [2001:db8::1]:443 -servername yourdomain) and confirm the same certificate and chain appear. The PacketTools SuperTool runs DNS, mail, and SSL checks for a domain in one pass.

    VPN leaks are the other trap. Some VPN clients tunnel only IPv4, leaving IPv6 traffic on your local connection. Connect the VPN, then check your public addresses again: if an IPv6 address from your ISP still appears, enable the client’s IPv6 leak protection or disable IPv6 on that interface.

    Plan for Both Protocols, Not an Instant Switch

    Treat IPv4 and IPv6 as two production stacks that you run, secure, and monitor together for years. IPv4 brings universal compatibility at the price of NAT and scarce addresses, while IPv6 brings address abundance, SLAAC, and direct reachability, and the two only interoperate through dual-stack hosts or translation.

    Keep your rollout order simple: confirm ISP prefix delegation, enable IPv6 on the core, match firewall and ACL rules across both stacks, publish correct AAAA records, then move outward to servers and users. Allow essential ICMPv6 and plan /64 subnets per segment.

    After every change, test each protocol on its own: public addresses, A and AAAA records, ping and traceroute over -4 and -6, the TLS certificate on the IPv6 listener, and IPv6 leak status with your VPN connected.

  • IP Scanner: Discover Devices Safely

    IP Scanner: Discover Devices Safely

    An IP scanner walks a range of addresses on a network you administer, records which hosts answer, and returns what it can learn about each one: address, hostname, MAC address, and sometimes open ports or shared folders. That output becomes the raw material for asset inventory, rogue device detection, and everyday troubleshooting when a printer vanishes or a subnet fills up faster than expected.

    A cybersecurity analyst monitors abstract network connections and scanning activity on several computer screens.

    Run discovery only against ranges you own or have written authorization to test, start with a passive or ping-level sweep before anything intrusive, and treat every result as a hypothesis until a MAC address or hostname confirms the asset. That sequence keeps scans defensible and keeps your inventory honest.

    PacketTools was built by a network and security engineer with more than 28 years of hands-on experience in enterprise IT, and the same diagnostic habits that verify VPNs and analyze routing in production apply directly to device discovery. By the end of this, you will be able to pick a discovery method that fits your environment, read the output without guessing, and know which findings deserve a follow-up before you touch a switch port.

    What Device Discovery Reveals on a Network

    https://www.youtube.com/watch?v=zYdRruF1g1w

    Discovery answers one question well: which addresses in a defined range currently respond. Everything else, hostname, vendor, operating system, service banner, is enrichment layered on top of that reachability signal, and each layer has its own failure mode.

    From IP Address to Hostname and MAC Address

    A network scanner starts with an address and works outward. The IP tells you where the host sits in the subnet. Reverse DNS may return a hostname, and on the local segment the ARP table gives you a MAC address whose first three bytes identify the vendor.

    That vendor prefix is the most useful field in a LAN scanner result. A MAC beginning with an Axis or Hikvision OUI on a corporate VLAN reads very differently from an Apple or Dell prefix, even before you know the device name.

    Where hostname resolution fails, the MAC often still lands. Where both fail, you have an address that answers and nothing more, which is a legitimate finding worth recording as such.

    Why a Reachable Host Is Not Always an Identified Asset

    Reachability and identity are separate data points. A host can reply to ICMP while blocking every port, refusing NetBIOS, and having no PTR record, leaving a row in your network inventory that says “something is here.”

    Firewalled endpoints, hardened Linux hosts, and IoT sensors with minimal stacks all produce this. Devices behind a router relative to your scan point show a MAC address belonging to that router, not the endpoint, which quietly breaks vendor identification.

    IPv4, IPv6, and Subnet Boundaries

    Scan scope follows the subnet, and this is where most incomplete inventories originate. A /24 sweep covers 254 usable hosts; a /16 covers over 65,000 and takes correspondingly longer.

    IPv6 changes the math entirely. A /64 holds 18 quintillion addresses, so brute-force sweeps are impractical, and a network IP scanner working in IPv6 relies on neighbor discovery, multicast, DHCPv6 leases, or DNS records instead of enumeration. Dual-stack hosts frequently appear twice, once per address family, and reconciling those into one asset record is manual work in most tools.

    How Authorized Discovery Methods Work

    Cybersecurity analyst reviewing network discovery visuals on multiple monitors in a modern enterprise office.

    Every discovery method sends probes and waits for responses, and the choice of probe determines what you find and what you miss. Ping sweeps find cooperative hosts, ARP finds everything on the local segment, SNMP interrogates managed gear directly, and port probing fills in service detail once scope and permission are settled.

    Ping Sweeps and Their Blind Spots

    An ICMP echo sweep is the fastest and least intrusive way to establish which addresses are live. Nmap’s -sn flag does exactly this, and it doubles as a sanity check that you are pointed at the right range before running anything heavier.

    The blind spot is predictable: hosts configured to drop ICMP appear dead. Windows endpoints with the default firewall profile, hardened servers, and many appliances all fall into that bucket. A ping sweep that returns 40 hosts on a segment you know has 60 endpoints is telling you about your probe, not your network.

    Our ping test is useful for the reverse case, confirming reachability and round-trip behavior for a single host you already know about.

    ARP, NetBIOS, and Local Network Visibility

    On your own broadcast domain, ARP is the honest method. A host cannot participate in IPv4 on the segment without answering ARP, so arp-scan and equivalent discovery find devices that ignore ICMP completely.

    The constraint is that ARP stops at the router. Off-segment ranges need a scan point inside that segment or a different technique.

    NetBIOS adds names on Windows-heavy networks, resolving workstation and workgroup identity where DNS records are missing. Older SMB-speaking devices and network printers often respond here when nothing else identifies them.

    SNMP Polling for Managed Infrastructure

    SNMP gives you the richest data on switches, routers, printers, and UPS units, because you are reading the device’s own MIB instead of inferring from packet behavior. Interface tables, ARP caches, and neighbor entries pulled from a core switch reveal hosts a sweep never touched.

    Use SNMPv3 with authentication and encryption. Community strings of public on production gear are a finding in their own right, not a convenience.

    Port and Service Probing in Approved Environments

    Port scanning follows host discovery: once you know an address is live, you determine which ports respond and what services sit behind them. HTTP and HTTPS management interfaces, FTP on legacy transfer boxes, SSH, and SMB shares are the common finds, and each produces an ip-port list you can compare against approved baselines.

    Two rules keep this safe. Get the authorization in writing with the target ranges named, and slow the timing on fragile equipment. Industrial and medical devices have been knocked offline by aggressive default timing, which is why conservative timing and identity-oriented scripting are standard practice for ICS and OT segments. Feed results into network monitoring so changes surface between scans.

    How to Read and Validate Scan Results

    A cybersecurity analyst reviews network scan results on dual monitors in a modern office.

    Scan results are evidence, not conclusions. Validation means separating “this device is unrecognized” from “this scan lacked the access to identify it,” then reconciling the surviving rows against what your records claim should exist.

    Distinguishing Unknown Devices From Incomplete Data

    Start with the fields that are blank. An entry with an IP, no hostname, no vendor, and no open ports usually means the probes were blocked, not that the device is exotic.

    Re-run the same address with a second method before escalating. An ARP query on the local segment, an SNMP poll of the switch the host connects to, or a NetBIOS name request each attacks the gap from a different angle. Vendor OUI lookups on the MAC often resolve identity when everything else stays quiet.

    Then check the wired path. Switch MAC address tables map a MAC to a physical port, which turns an abstract row into a cable you can trace. That step converts more unknowns than any additional scan flag.

    Finding Duplicate Addresses and Stale Records

    Two hosts answering for one IP produces intermittent, maddening symptoms: sessions that drop mid-transfer, ARP entries that flip vendor prefixes between polls. Compare MAC addresses across consecutive scans of the same range and duplicates surface immediately.

    Stale records run the other direction. Addresses in your inventory that no longer respond, DHCP reservations for decommissioned hardware, DNS entries pointing at reassigned IPs. Each one is a future misdiagnosis, and each one is cheap to clear once you have two scans to compare.

    Timestamp every export. Scans run at 3 a.m. and 3 p.m. on the same subnet return different host counts, and without timestamps you cannot tell drift from noise.

    Turning Discovery Data Into Asset Management Evidence

    Discovery becomes useful for asset management when each row carries provenance: scan date, method used, scope, and who authorized it. Continuous asset visibility of this kind is a prerequisite for a never trust, always verify model, which is why zero trust programs start with inventory work.

    Reconcile the export against your CMDB, tag unexplained hosts with an owner and a due date, and keep the raw file. When a network security question comes up six months later, dated evidence settles it.

    Which Tool Fits the Environment?

    Tool selection follows the question you are answering: a one-off reachability check, a repeatable subnet sweep for a spreadsheet, a scripted scan feeding a pipeline, or a platform that tracks assets without you starting anything.

    Browser tools Angry IP Scanner Nmap Inventory platforms
    Install required No Yes Yes Yes, plus agents/collectors
    Platforms Any browser Windows, Mac, Linux Windows, Linux, macOS Server or SaaS
    Scriptable output Limited Multiple export formats Full (XML, grepable) API and reporting
    Best for Single-host checks Fast range sweeps Precise, documented scans Continuous inventory
    Cost Free Free, open source Free, open source Licensed

    Browser-Based Checks vs. Local Discovery Software

    Browser tools handle the checks that do not require touching every address in a range: confirming your public address, resolving a record, testing a certificate, verifying reachability from outside the LAN. PacketTools runs these in real time with no sign-in and no logging of IPs, queries, or test data, which matters when the target is a client’s production edge.

    Sweeping an internal /24 needs software on a host inside that subnet. No browser can send ARP requests to your LAN, so local discovery software remains the tool for full-subnet enumeration. The what is my ip check is the fastest way to establish which public address your scan traffic will originate from before you request authorization.

    When Command-Line Control Matters

    Nmap earns its place when you need exact control over probe type, timing, and output format. nmap -sn 10.10.20.0/24 for a discovery-only sweep, timing templates to throttle fragile segments, XML output that parses cleanly into a report.

    That precision is also documentation. A saved command plus its XML output proves what you ran, against what, and when. Ethical practice here is explicit: scan only networks you own or have written permission for, since unauthorized scanning can violate the Computer Fraud and Abuse Act.

    Desktop Options for Windows, macOS, and Linux

    Angry IP Scanner is the cross-platform default: free, open source, runs on Windows, Mac, and Linux, scans address and port ranges, exports to several formats. It is the tool to reach for when someone asks for a device list in the next ten minutes.

    Famatech’s Advanced IP Scanner is Windows-only and adds shared folder access plus RDP and Radmin launch shortcuts from the results grid. SoftPerfect Network Scanner runs on Windows, macOS, and Linux, and retrieves device detail over WMI, SNMP, HTTP, SSH, and PowerShell, which suits mixed environments where one protocol is never enough.

    Fing covers the mobile and home side, identifying device brand, model, and OS during the scan.

    When Continuous Inventory Platforms Are the Better Fit

    Manual scans go stale the moment they finish. Platforms like Lansweeper suit environments where devices join and leave daily, agents and credentialed collection fill in software inventory, and audit trails need to exist without anyone remembering to run a sweep. Lansweeper does not publish flat pricing publicly; licensing scales with asset count.

    The tradeoff is deployment weight and credential management. For a 40-device office, a scheduled Angry IP Scanner export into a dated spreadsheet holds up fine.

    Using Discovery Data Safely in Home and Managed Networks

    Authorization comes before the first packet, and what you do with the output matters as much as how you collected it. Managed networks need documented scope and change-window timing; a home LAN needs a baseline you can compare against next month.

    A Permission-First Process for Managed Networks

    Written authorization naming the exact CIDR ranges, the scan window, the methods permitted, and a named contact who can stop the scan. Network administrators who skip this step end up explaining themselves to a security team mid-scan.

    Then work in stages. Passive collection and SNMP polling first, ICMP discovery second, port probing last and only within the approved scope. Notify the monitoring team so your sweep does not open an incident ticket, and avoid production change freezes.

    Record what you ran. Command, timestamp, operator, and output file, stored alongside the authorization.

    A Practical Home LAN Inventory Example

    Start by finding your subnet: check your router’s LAN page or run ipconfig on Windows or ip addr on Linux. A typical home range is 192.168.1.0/24.

    Scan that range with Angry IP Scanner or Fing and export the results. Then walk the physical space and match each responding host to something you can see: thermostat, TV, doorbell, tablet in a drawer.

    Rename anything identifiable in your router’s DHCP table and set static reservations for the printer and NAS. That single pass converts a wall of addresses into a list you can compare against, and it is the fastest way to find the smart plug you forgot about. When a device shows up in the scan but the internet is unreachable from it, our guide on wifi connected but no internet covers the layered checks.

    What to Check After an Unexpected Device Appears

    Do not start with a takedown. Pull the MAC address and look up the vendor prefix, since most surprise devices resolve into a known brand of streaming stick, smart bulb, or guest phone.

    If it stays unidentified, find its switch port or check whether it associated over wireless, then look at what it talks to. A device beaconing to unfamiliar destinations is a different problem from one sitting idle.

    Isolation before removal: move it to a guest VLAN or block it at the firewall while you confirm ownership. Rotate the Wi-Fi PSK if wireless access is the likely entry point, and check whether RDP or Radmin is reachable from that segment.

    Extending Troubleshooting With PacketTools

    Discovery tells you a host exists; the follow-up questions are about whether it works. Our free network tools cover the layers a sweep does not touch, with no sign-in and nothing logged.

    When a host responds to a scan but its name will not resolve, the dns propagation checker and dns lookup failed walkthrough narrow it down. For path problems between segments, how to trace a route explains reading hop-by-hop output. Domain-wide checks, DNS, MX, SPF, DKIM, DMARC, blacklist, and SSL, run together in the super tool.

    Building Reliable Visibility Without Overreaching

    An IP scanner earns its keep when the scope is authorized, the method matches the segment, and the output gets validated before anyone acts on it. ARP finds what ICMP misses on the local wire, SNMP fills in managed infrastructure, and port probing waits for written permission naming the ranges.

    Read results as evidence with gaps: blank hostname fields point at blocked probes more often than mystery hardware, and a MAC vendor lookup or a switch port trace resolves most of what a network scan leaves ambiguous. Timestamp exports, compare consecutive runs, and clear stale records as you go.

    Pick the lightest tool that answers the question. A browser check for a single host, Angry IP Scanner for a subnet list you need this afternoon, Nmap when the command and its output have to stand as documentation, a continuous platform when devices change faster than you can schedule sweeps. Keep the authorization filed with the results, and your network security and asset management records stay defensible.

  • DNS Lookup Failed: Causes and Troubleshooting Steps

    DNS Lookup Failed: Causes and Troubleshooting Steps

    A DNS lookup failed message means one specific thing: the resolution chain that turns a domain name into an IP address broke somewhere between your stub resolver and the authoritative nameservers. Everything else, the browser error string, the application timeout, the failed API call, is downstream noise. Your job is to find which hop stopped answering.

    A workstation and network equipment with an interrupted connection between the computer and server.

    Work the resolution path in order (client cache, stub resolver, recursive resolver, authoritative nameserver, zone data) and a DNS lookup failure narrows to a single fault domain in under five minutes. That order matters because each layer can mask the one behind it, and flushing a cache before you know whether the domain even delegates correctly wastes the outage window.

    PacketTools was built around exactly this workflow. The same DNS Lookup, DNS Propagation Checker, and SuperTool queries used here run in production networks to verify delegation, compare resolver answers, and confirm records before a change goes live. No sign-in, no logging of your queries, no stored test data.

    By the end, you will be able to read an NXDOMAIN, a SERVFAIL, and a bare timeout as three different diagnoses, and know which one belongs to you and which one belongs to the domain owner.

    What the Error Reveals About the Resolution Path

    An IT engineer examines a network with a broken connection path between devices and servers.

    The exact response code your resolver returns tells you how far the query traveled before it died. A domain that returns NXDOMAIN reached authoritative DNS and got a definitive “no such name.” A query that times out may never have left your NIC.

    How a Recursive Resolver Reaches Authoritative DNS

    Your stub resolver hands the query to a recursive resolver, which walks the hierarchy from root to TLD to the domain’s nameservers.

    The recursive resolver asks a root server for .com nameservers, asks those for the domain’s NS records, then asks the authoritative nameserver for the A record, AAAA record, or CNAME record you requested. Each step is cached against its TTL.

    Break any link and the symptom changes. A missing NS record at the parent zone kills the referral. A dead authoritative host kills the final answer. A broken CNAME target resolves halfway and then returns nothing usable.

    NXDOMAIN vs. SERVFAIL vs. Timeout Responses

    These three responses point at three different owners of the problem.

    Response What it means Where to look
    NXDOMAIN Authoritative DNS confirms the name does not exist Typo, deleted record, expired domain
    SERVFAIL Resolver tried and could not complete the lookup DNSSEC validation failure, broken delegation, unreachable nameserver
    Timeout No response at all within the grace period Blocked UDP port 53, unreachable resolver IP, firewall drop

    SERVFAIL is the one engineers misdiagnose most. It is a resolver-side failure report, so the domain can be perfectly configured while your validating resolver rejects the chain.

    Why 504 DNS Lookup Failed Is a Different Failure Mode

    A 504 DNS lookup failed comes from a proxy, CDN edge, or gateway, telling you its resolver could not resolve your origin hostname.

    Your workstation resolves the site fine because you are hitting the edge, which then fails to look up the backend. Check the origin hostname in your CDN configuration, the origin’s A record, and whether the origin nameservers answer queries from outside your network.

    Is the Fault Local, Network-Wide, or Domain-Side?

    IT professional examines network connections and server systems in a modern operations center.

    Scope the blast radius before touching a single setting. One device failing, every device on the LAN failing, and one domain failing everywhere are three separate investigations with almost no overlap in remediation.

    What It Means When Only One Device Fails

    A single failing host points at that host’s DNS configuration, cache, or a local override.

    Test the same name from a phone on mobile data and from a second machine on the same subnet. If both succeed, the fault sits in the endpoint’s resolver settings, a stale cache entry, a hosts file line, or a VPN client that rewrote the DNS servers on the network adapter.

    Windows checks its cache first, then the hosts file, then queries the DNS server, according to Microsoft’s client name resolution guidance. A stale hosts entry produces zero DNS traffic on the wire, which is why packet captures look empty during these failures.

    How to Separate Wi-Fi and ISP Problems From DNS

    Ping an IP address directly. If ping 1.1.1.1 succeeds and name resolution fails, connectivity is fine and DNS is the problem.

    When the ping also fails, you are chasing a Wi-Fi, modem, or ISP path issue, not resolution. That is the difference between a resolver fault and a Wi-Fi connected but no internet condition, and the fixes share nothing.

    DHCP hands out ISP DNS by default. When an ISP resolver has a partial outage, some names resolve and others fail, which reads like a random site problem until you compare against a public resolver.

    When One Domain Fails but Other Sites Resolve

    A single domain failing across multiple networks and resolvers is a domain-side fault.

    Check registration status and nameserver delegation first. An expired domain, a registrar hold, or nameservers that were changed at the registrar but never populated at the DNS provider all produce the same user-facing failure.

    Recent record changes bring TTL into it. A DNS propagation delay means old cached answers persist for the length of the previous TTL, and CDN edges hold their own cached views independently.

    Run the First DNS Tests Before Changing Settings

    Diagnose before you remediate. Four minutes of resolver comparison and a dig +trace will tell you whether the fault is your resolver, the transport path, or the domain’s zone, and that answer determines every step after it.

    Compare Local, Google, Cloudflare, and Quad9 Resolver Results

    Query the same name against your configured resolver and three public DNS servers, then compare.

    • Google DNS: 8.8.8.8 and 8.8.4.4
    • Cloudflare DNS: 1.1.1.1 and 1.0.0.1
    • Quad9: 9.9.9.9

    If your local resolver fails while all three public resolvers answer, the fault is your resolver or ISP DNS. If every resolver fails identically, the domain or its delegation is broken. If public resolvers work and your local one returns a different answer, suspect split DNS or interception.

    Quad9 filters known-malicious domains, so a name that resolves on 1.1.1.1 and returns NXDOMAIN on 9.9.9.9 is a reputation block, not a configuration error.

    Use nslookup and dig to Identify the Break

    dig gives you the status line and the full chain; nslookup ships on every Windows box.

    dig example.com A +short
    dig @8.8.8.8 example.com A
    dig example.com NS
    dig +trace example.com

    +trace walks root to TLD to authoritative, and where it stops is where delegation breaks. Failing early in the trace points at domain registration or the parent zone’s NS records.

    On Windows, nslookup example.com 8.8.8.8 forces a specific server. Note that nslookup contacts only the primary configured DNS server, so on a NIC with four resolvers listed it will report failure even when a secondary would have answered. Windows uses nslookup while macOS and Linux use dig for the same class of test.

    Read the status: field in dig output. NOERROR with an empty ANSWER section means the name exists but the record type you asked for does not.

    Check Reachability and the DNS Path With Ping and Traceroute

    DNS rides UDP port 53 with TCP fallback for large responses, so confirm that transport actually works.

    Ping the resolver IP. A resolver that does not answer ICMP still may serve DNS, so follow with dig @<resolver-ip> example.com to test port 53 directly. Run a ping test against the resolved IP once you have an answer to separate resolution from reachability.

    Traceroute the resolver address when queries time out on an internal DNS server. Path asymmetry, a firewall hop that drops UDP, or an MPLS re-route shows up in the hop list. Our guide on how to trace a route covers reading those hops properly.

    Validate a Domain With PacketTools DNS Lookup and SuperTool

    Command-line tools show you what your vantage point sees. External validation shows what the rest of the internet sees.

    The PacketTools DNS Lookup runs the query from outside your network, so a name that fails locally and resolves externally confirms the fault is inside your perimeter. SuperTool bundles DNS, MX, SPF, DKIM, DMARC, blacklist, and SSL checks into a single domain run, which is faster than firing six separate queries when a domain’s records are suspect.

    Nothing is logged. No IPs, no queries, no test data, no sign-in.

    Fix Endpoint Resolver and Cache Problems

    Endpoint fixes are cheap and reversible, which is why they come after diagnosis and before anything touching production DNS. A corrupted cache, a stale static resolver entry, or a VPN client override accounts for most single-machine failures.

    Clear a Corrupt DNS Cache on Windows, macOS, and Linux

    Flush the cache when a record changed recently and your machine still returns the old IP address.

    • Windows: ipconfig /flushdns from an elevated Command Prompt
    • macOS: sudo dscacheutil -flushcache; sudo killall -HUP mDNSResponder
    • Linux (systemd-resolved): sudo resolvectl flush-caches
    • Linux (nscd): sudo systemctl restart nscd

    Verify after flushing with dig and check the TTL value in the response. A TTL counting down from the record’s full value means you received a fresh authoritative answer; a low odd number means you hit a cache again.

    Google Chrome keeps its own cache at chrome://net-internals/#dns. Clear that separately, since flushing the OS cache leaves it untouched.

    Verify DHCP and Static DNS Configuration

    Check what DNS servers the adapter is currently using before assuming DHCP delivered them.

    Run ipconfig /all on Windows or resolvectl status on Linux. A static entry pointing at a decommissioned internal DNS server is a common leftover from a lab build or an old migration.

    Multiple unreachable servers listed ahead of a working one cause resolution to take roughly four seconds while the client cycles through the list. Applications time out before DNS does. Remove dead entries in the TCP/IPv4 properties rather than adding more.

    Reset the Windows Network Stack Only When Needed

    Reserve stack resets for cases where the adapter configuration looks correct and queries still never leave the machine.

    netsh winsock reset
    netsh int ip reset

    Both require a reboot and will clear proxy settings, static routes, and any LSP entries installed by security software. Capture the current config first. This is the step that fixes DNS_PROBE_FINISHED_BAD_CONFIG conditions when nothing lighter has, and our walkthrough on DNS_PROBE_FINISHED_BAD_CONFIG covers the sequence in more detail.

    Check Browser, Hosts File, VPN, and Proxy Overrides

    Something between the application and the resolver is rewriting your query more often than you would expect.

    Inspect C:WindowsSystem32driversetchosts or /etc/hosts for leftover entries. A hosts entry produces an answer with no DNS traffic on the wire at all.

    Then check for a VPN client that pushed its own DNS servers, an Android Private DNS profile still pointed at a decommissioned DoT host, and browser-level DNS-over-HTTPS that bypasses your corporate resolver entirely. Clearing cookies fixes nothing here; the override is at the resolver layer.

    Resolve Network, Security, and Authoritative DNS Faults

    Once the endpoint is clean, the remaining faults live in the transport path or the zone itself. Blocked port 53, split-horizon views that leak, broken delegation, and DNSSEC chain failures each produce distinct signatures.

    Allow DNS Transport Through Firewalls, Filters, and Relays

    An outbound rule blocking UDP port 53 produces a timeout with zero DNS traffic reaching the server.

    Microsoft documents this precisely: with UDP 53 blocked, Resolve-DnsName returns an operation timeout and a Wireshark trace on the client shows no outbound DNS at all. Mirror the switch port to confirm whether the packet ever left the host.

    Allow TCP 53 as well. Large responses, DNSSEC records, and zone transfers fall back to TCP, and a UDP-only rule breaks them selectively. Content filters and router DNS relays add another failure point when the relay itself points at a dead upstream.

    Diagnose Split DNS on Corporate Networks and VPNs

    Split DNS breaks when the client resolves an internal name against an external resolver, or the reverse.

    Compare dig @<internal-dns> intranet.corp.example with dig @1.1.1.1 intranet.corp.example. Internal-only zones return NXDOMAIN publicly by design, so a public NXDOMAIN on an internal name is correct behavior and tells you the query went to the wrong resolver.

    Check the VPN’s DNS suffix search list and split-tunnel rules. A long suffix search list makes the client append each domain in order, adding seconds of latency before the correct query is even sent.

    Repair Delegation, Zones, and Missing Records

    Delegation faults show up as SERVFAIL or an early stop in dig +trace.

    Query the parent zone for NS records with dig example.com NS @<tld-server> and compare against what the DNS provider actually serves. Registrar nameservers and provider nameservers must match exactly.

    Then confirm the record itself exists. An A record deleted during a migration, a CNAME pointing at a hostname that no longer resolves, or an AAAA record for an IPv6 address that is not routed all produce failures for clients that prefer that record type.

    Handle DNSSEC Failures and Propagation Safely

    A DNSSEC validation failure returns SERVFAIL on validating resolvers while non-validating resolvers answer normally.

    Test with dig +cd example.com to disable validation. An answer with +cd and SERVFAIL without it confirms a broken chain, almost always a DS record at the registrar that no longer matches the zone’s DNSKEY after a key rollover.

    Lower TTLs to 300 seconds at least 24 hours before a planned change, then verify the new records across regions with a propagation check before restoring the original TTL. Testing changes on a staging domain that mirrors production is standard practice, as outlined in safe pre-launch DNS testing.

    Turn DNS Evidence Into the Right Next Action

    Every DNS lookup failed error resolves into one of four owners: your endpoint, your network path, your resolver, or the domain’s authoritative DNS. The response code and the resolver comparison identify which one before you change anything.

    Work the sequence. Compare your resolver against 8.8.8.8, 1.1.1.1, and 9.9.9.9. Run dig +trace to see where delegation stops. Flush the cache only when a record changed recently. Reset the Windows stack only when queries never leave the NIC.

    For domain-side faults, verify delegation and records externally with the PacketTools DNS Lookup and confirm timing with the propagation checker before you tell a stakeholder the change is live. When a broader outage is in play, our network troubleshooting and DNS server not responding guides pick up where resolution testing leaves off.

    Keep the four public resolver IPs and dig +trace in your runbook. Those two things answer the ownership question faster than any log dive.

  • DNS Probe Finished Bad Config: Fix DNS Settings

    DNS Probe Finished Bad Config: Fix DNS Settings

    When Chrome throws DNS_PROBE_FINISHED_BAD_CONFIG, the browser is telling you it asked the resolver for an address and the resolver configuration on that machine or network was broken enough that the query never produced a usable answer. The site is probably fine. Your DNS path is not.

    A network administrator examines disconnected network diagrams on monitors in a server operations center.

    Work the problem in this order: confirm the domain resolves publicly, flush the local resolver cache, verify the adapter’s DNS server addresses, then rule out VPN, proxy, and security software. Most tickets close somewhere in the first two steps, and the remaining ones almost always trace back to a static DNS entry someone set months ago and forgot about.

    At PacketTools we use these same diagnostics in production networks to verify VPNs and analyze routing, so the sequence below is the one that survives contact with real endpoints. You will finish with a repeatable triage path you can hand to a junior tech, plus a way to prove whether the fault sits on the device, the network, or the domain itself.

    What the Error Indicates During DNS Resolution

    Network administrator examining monitors showing disrupted connections in a server environment.

    This error fires when the stub resolver on the device cannot complete a DNS lookup because of the configuration it was handed, whether that came from DHCP, a static entry, a VPN client, or a router. The domain name may exist perfectly well in public DNS while the client still fails, which is what separates this code from a genuine missing-record failure.

    How a Domain Name Becomes an IP Address

    Chrome hands the domain name to the operating system’s resolver. The resolver checks its cache, then queries the configured DNS server, which walks the domain name system hierarchy until an authoritative name server returns an A record with an IPv4 address (or AAAA for IPv6).

    Only after the browser holds that IP address can it open a TCP connection to the web server. Break any link in that chain, the DNS server addresses, the route to them, or the cached entry, and the URL never gets a destination.

    Why a Bad Configuration Differs From NXDOMAIN

    NXDOMAIN means an authoritative server answered and said the non-existent domain has no record. Bad config means the answer never came back cleanly at all.

    Signal Bad Config NXDOMAIN
    Who answered No usable reply from resolver Authoritative server replied
    Domain exists Usually yes No
    Fault location Device or network DNS records
    Fixed by changing resolver Frequently No

    That distinction matters when you triage. Bad config points to misconfigured settings at the device or network level, so stop editing zone files and start checking adapters.

    How the Message Appears Across Browsers and Operating Systems

    Chrome shows the literal string. Firefox reports “We’re having trouble finding that site,” Safari says it cannot find the server, and Opera renders the same Chromium text since it shares the engine.

    The underlying failure is identical on Windows, macOS, Linux, Android, and iPhone. Only the wording changes, so never assume a browser-specific bug when a second browser on the same endpoint fails too.

    Is the Failure on the Device, Network, or Domain?

    An IT professional investigates a connectivity problem involving a computer, wireless router, and network server.

    Isolate the fault domain before you touch a single setting: test more than one hostname, test a second network connection, and query both the configured resolver and a public one. Three minutes of scoping saves you from resetting a network stack that was never broken.

    Test Multiple Domains and a Second Network Connection

    Load three unrelated domains. If every one fails, the resolver path is broken; if only one fails, look at that domain’s DNS records or a filtering policy.

    Then move the endpoint to a phone hotspot. Working over cellular and failing on the office Wi-Fi or Ethernet points at the router, the VPN, or the internet service provider’s resolvers. Failing on both keeps the fault on the device.

    Query the Configured Resolver and a Known Public Resolver

    Open a command prompt or terminal and query directly, bypassing the browser entirely:

    nslookup packettools.com
    nslookup packettools.com 8.8.8.8

    On Linux or macOS, dig @1.1.1.1 packettools.com +short does the same job. When the second query returns an address and the first times out, the configured DNS server is the problem, not the domain. That pattern also produces the classic DNS server not responding symptom on the same box.

    Keep the public DNS servers handy: Google DNS at 8.8.8.8 and 8.8.4.4, Cloudflare at 1.1.1.1 and 1.0.0.1.

    Use PacketTools to Check Public DNS Records Independently

    Local tools inherit local breakage. Run the lookup from outside your network with the DNS propagation checker to see what resolvers worldwide return for the domain.

    If public results come back clean and consistent, the domain’s DNS records are fine and your remaining work is entirely client-side. PacketTools logs no IPs, queries, or test data, which makes it safe to run against internal-facing hostnames during a live incident.

    Restore Basic Network Connectivity First

    Before editing DNS settings, confirm the endpoint holds a valid lease and can reach its gateway. A device with a 169.254.x.x address or a missing default route will throw DNS errors that have nothing to do with DNS configuration.

    Restart the Modem, Router, and Affected Endpoint

    Power off the modem and wi-fi router, wait sixty seconds, bring the modem up first and let it sync before powering the router. Reboot the endpoint last.

    This clears the router’s own DNS forwarder cache and forces a fresh DHCP lease. One recurring report on Microsoft Q&A describes the error hitting three home PCs every other day, fixed each time by a router reset, which is the signature of a failing forwarder rather than a client fault.

    Confirm DHCP Has Supplied a Valid Address and Gateway

    Check the assigned address, then renew it:

    ipconfig /all
    ipconfig /release
    ipconfig /renew

    On macOS, use System Settings > Network > Details > TCP/IP > Renew DHCP Lease. On Linux, sudo dhclient -r && sudo dhclient on the relevant network adapter.

    Verify three things in the output: a routable IPv4 address, a default gateway on the same subnet, and DNS server entries that make sense for the network. Ping the gateway to confirm layer 3 works before blaming name resolution.

    Identify Router-Wide Failures and Managed-Network Limits

    When every device on the segment fails identically, stop working the endpoint. Log into the router settings and inspect the WAN DNS entries, any DNS filtering feature, and the firewall rules that might block outbound port 53.

    On corporate or guest networks you often cannot change these. Document what resolves and hand it to whoever owns the network configuration, since local changes get overwritten by policy anyway.

    Repair DNS Cache and Adapter Configuration

    This is where the fix lands for most cases: clear the poisoned cache, put the DNS server addresses back to something known-good, and confirm the adapter bindings were not quietly changed by an installer or an old VPN client.

    Flush the Local Resolver Cache on Windows, macOS, and Linux

    Run these from an elevated command prompt or terminal:

    • Windows: ipconfig /flushdns
    • macOS: sudo dscacheutil -flushcache; sudo killall -HUP mDNSResponder
    • Ubuntu / systemd Linux: sudo systemd-resolve --flush-caches (or resolvectl flush-caches on newer releases)

    Chrome keeps its own cache too. Visit chrome://net-internals/#dns and clear the host cache, then chrome://net-internals/#sockets and flush socket pools. Skipping the browser-level flush is why a correct fix sometimes appears not to work.

    Set DNS Back to DHCP or Use a Trusted Public DNS Server

    Open the adapter properties, select Internet Protocol Version 4 (TCP/IPv4), and set DNS to obtain automatically. If the network’s own resolver is the failure, hardcode a public DNS server instead:

    Provider Primary Secondary
    Google DNS 8.8.8.8 8.8.4.4
    Cloudflare 1.1.1.1 1.0.0.1

    From the command line: netsh interface ip set dns name="Ethernet" static 8.8.8.8 then netsh interface ip add dns name="Ethernet" 8.8.4.4 index=2.

    A DNS misconfiguration left behind by uninstalled security software shows up here constantly, usually as a loopback or 10.x address nothing answers on.

    Check TCP/IPv4, Static Addressing, and Adapter Bindings

    Look for a static IPv4 address that no longer matches the subnet, a stale secondary DNS entry, or IPv6 handing back an unreachable resolver while IPv4 looks correct.

    Disable any leftover virtual adapters from VPN clients or hypervisors, and confirm the physical adapter sits above them in the binding order. Two adapters supplying conflicting DNS server addresses produce intermittent failures that survive every cache flush you throw at them.

    Reset the Windows Network Stack Only When Needed

    Treat this as the last configuration step, because it wipes custom routes, static entries, and Winsock LSPs:

    netsh winsock reset
    netsh int ip reset
    ipconfig /flushdns

    Reboot afterward. Windows 11’s Network Reset under Settings > Network & Internet > Advanced does the same thing plus reinstalls network adapters, and it removes VPN clients, so document what needs reinstalling first.

    Remove Software and Browser Interference

    When the adapter is clean and public lookups resolve, something running on the endpoint is intercepting or rewriting DNS. VPN clients, proxy settings, and antivirus web-filtering modules are the usual culprits, in that order.

    Clear Stale Browser Data and Test Without Extensions

    Open Chrome’s clear browsing data dialog (Ctrl+Shift+Delete), select cached images, files, and cookies for all time, and clear. Delete temporary files while you are there.

    Then launch an incognito window, which disables browser extensions by default. Resolution working in incognito and failing in a normal window narrows it to an extension, frequently an ad blocker or a security add-on with its own DNS-over-HTTPS setting. An outdated browser build is worth ruling out too: check chrome://settings/help and let any pending update install.

    Disconnect VPN and Review Proxy Settings

    Disconnect the VPN completely and retest. Many clients push their own resolvers and leave them behind after an ungraceful disconnect, so verify with ipconfig /all that the DNS entries reverted.

    Check Windows Settings > Network & Internet > Proxy and clear any automatic configuration script or manual proxy server the reader did not deliberately set. Malware and old corporate images both leave proxy entries that silently break name resolution.

    Check Firewall and Security Software DNS Controls

    Temporarily disable third-party antivirus web protection and retest, then re-enable it. Windows Defender Firewall rarely blocks outbound 53, though custom rules from a previous admin do.

    Suites with DNS filtering or “secure DNS” features redirect queries to their own resolvers. When the vendor’s resolver is unreachable, every lookup fails while the rest of the connection stays up. Whitelisting or turning off that single module usually restores service without removing the product.

    Update Network Drivers When the Adapter Is Unstable

    Open Device Manager, expand Network adapters, and check the driver date against the vendor’s current release. Pull the driver from the NIC or laptop manufacturer, since Windows Update often ships a generic build that drops connections under load.

    Flapping links produce sporadic DNS failures that look like configuration problems. If the adapter logs disconnects in Event Viewer, fix the driver before spending more time on resolver settings, and review the broader network troubleshooting path for anything physical.

    A Repeatable Path to Working DNS

    The sequence holds regardless of platform: scope the failure with a DNS lookup against a second resolver, confirm the public DNS records look correct, restore connectivity, flush caches, then fix the network configuration on the adapter. Software interference comes last because it is the least common cause and the most disruptive to test.

    Keep a note of what you changed on each endpoint. Static DNS entries and leftover VPN adapters are the two findings that repeat most across tickets, and both are trivial to spot once you know the order to check them in.

    When the endpoint is clean and the problem persists across every device on the segment, the fault sits with the router configuration or the internet service provider’s DNS server, and that is a call to make rather than a setting to change. Run the domain through the PacketTools network tools before you make that call so you have propagation and record data in hand.